如何通过 Google Vids API 用 Gemini Omni 1.2 Flash 生成会说话的数字人视频(中文教程)
12 分钟阅读 • 2026 年 10 月 8 日(2026 年 11 月 9 日更新)
目录
- 简介
- 为什么选 Google Vids API
- Google Vids API 价格与额度
- 如何绑定 Google 账号
- 调用方式:同步、异步与 Webhook
- 实战:两个数字人发布一款球鞋
- 生成效果示例
- 用一张照片做会说话的数字人
- 单独生成语音
- 常见问题
- 结语
简介
useapi.net 的 Google Vids API 用你的 Google Vids 网站订阅(Google AI Pro 或 Ultra),通过 REST 接口调用 Google Vids 里的 Gemini Omni 1.2 Flash:生成最长 15 秒、带声音和对白的视频,延长到约 34 秒,还能创建带固定配音的数字人(avatar),让它在视频里说出你写的台词,或者逐字念出你的稿子,生成最长 30 秒的口播视频。同一套音色也能单独把文字转成语音。
Google Vids 是 Google Workspace 里的视频应用,Google 在 2026 年 9 月为它加入了 Gemini Omni(Google 官方公告),2026 年 11 月 5 日升级为 Gemini Omni 1.2 Flash,单条视频最长 15 秒(Google Workspace 更新公告),Vids 网页里只显示为“Omni”。截至 2026 年 10 月,Google 没有公开 Vids 的视频生成 API,本 API 是第三方实现,生成在你的 Google 账号上进行,消耗的是订阅每月包含的 Vids 视频秒数,不按次付费。
Omni 1.2 Flash 在 Flow 和 Vids 中的对比、15 秒视频和每条视频价格:见Gemini Omni 1.2 Flash API 中文教程。
本文由 useapi.net 维护者撰写,介绍的是我们自己的托管 API,示例代码开源在 GitHub。
为什么选 Google Vids API
- 没有验证码。Google Flow 每次生成都要过 reCAPTCHA,需要接打码服务。Google Vids 没有这一步,不用打码,也没有打码费用。
- 独立的额度。Vids 有自己的月度额度,不消耗 Google Flow 的积分。同一个 Google 账号同时绑定 Vids API 和 Google Flow API,两份额度都能用上。
- 可以延长 Omni 视频。POST /videos/extend 每次加 3 到 10 秒,只延长 24 秒以内的视频,所以最长约 34 秒。
- 带配音的数字人。从 30 种 Gemini 音色里选一种,配上一张人物图片保存为数字人,之后在任何视频里用
avatarId引用,人物用自己的声音说台词。数字人可以从你自己的照片开始,用一句话换装换景,再用 POST /videos/avatar 念出最长 30 秒的稿子。 - 时长 3 到 15 秒(按 1 秒递增),
720p或1080p,横屏或竖屏,两种分辨率消耗相同。
| Google Vids API | Google Flow API | |
|---|---|---|
| 额度 | 每月若干秒视频,与 Flow 分开 | 每月 Flow 积分 |
| 一条 10 秒 Omni 视频 | 10 秒额度,720p 或 1080p | Omni 1.1 15 积分,Omni 1.2 30 积分(720p,可免费放大到 1080p) |
| Ultra(199.99 美元)每月可生成的 10 秒 Omni 视频 | 约 1,000 条(10,000 秒,家庭方案共享) | 约 1,666 条 Omni 1.1(25,000 积分) |
| Omni 时长 | 3 到 15 秒,按 1 秒递增 | Omni 1.2:3 到 15 秒。Omni 1.1:4、6、8 或 10 秒 |
| 延长 Omni 视频 |  每次 3 到 10 秒,源视频最长 24 秒,最终最长约 34 秒 | 用 Omni 1.2,每次 3 到 10 秒,需付费套餐 |
| 验证码 | 无 | 每次生成都要 reCAPTCHA |
| 其他模型 | — | Veo 3.1、最高 4K 的 Nano Banana 图片 |
Google Vids API 价格与额度
一条 Gemini Omni 1.2 Flash 视频在官方 Gemini API 上按秒计费,在 Google Vids 上则消耗订阅每月包含的视频秒数(2026 年 11 月)。每个订阅每月有固定的秒数,一条视频用掉等于其时长的秒数,所以一条视频的成本就是它在订阅费里所占的份额。会说话的数字人口播视频和语音不消耗视频秒数,各有自己的月度计数(见下方额度说明)。
| 模型 | 官方 API | Ultra $199.99/月 每月 10,000 秒 | Pro $19.99/月 每月 500 秒 |
|---|---|---|---|
| Omni 1.2 Flash 720p,15 秒 | $1.04 $0.07/秒 | $0.30 / 15 秒 每月 666 条 | $0.60 / 15 秒 每月 33 条 |
| Omni 1.2 Flash 1080p,15 秒 | $1.56 $0.104/秒 | $0.30 / 15 秒 每月 666 条 | $0.60 / 15 秒 每月 33 条 |
| Omni 1.2 Flash 720p,10 秒 | $0.70 $0.07/秒 | $0.20 / 10 秒 每月 1,000 条 | $0.40 / 10 秒 每月 50 条 |
| 数字人口播视频 最长 30 秒 | 无 API | $0 / 0 秒 1 次 AI 数字人视频 | $0 / 0 秒 1 次 AI 数字人视频 |
| 语音 | 无 API | $0 / 0 秒 1 次 Gemini 使用 | $0 / 0 秒 1 次 Gemini 使用 |
- 同一个 Ultra 账号的 Google Flow 积分还能另外生成 Omni 视频,见 Google Flow 价格表。
- 套餐价格是 Google 订阅页面上的美国价格。
各套餐的 Vids 额度
Google 按月计量 Vids:视频按秒,图片按张。以下为 Google 在 Gemini in Google Vids 帮助页公布的数字:
| Google AI Plus | Google AI Pro | Google AI Ultra 5x | Google AI Ultra 20x | |
|---|---|---|---|---|
| AI 视频 | 每月 60 秒 | 每月 500 秒 | 每月 2,500 秒 | 每月 10,000 秒 |
| 图片生成与编辑 | 每次图片操作 1 点 | 每月 30 张 | 每月 300 张 | 每月 1,000 张 |
我们在真实账号上测得(2026 年 10 月):
- Google AI Ultra(199.99 美元)就是 Google 所说的 Ultra 20x:每月 10,000 秒视频、1,000 张图片。
- 视频秒数由 Google One 家庭方案的所有成员共享,图片按账号计算。多绑定同一家庭方案的账号,能增加图片额度和并行任务数,但不增加视频秒数。
- 免费 Google 账号在 Vids 里是 0 秒视频、0 张图片,Omni 视频和图片任务会跳过它。它仍然可以绑定,我们测试时(2026 年 11 月)它能创建数字人、生成口播视频和语音,每月有 10 次 AI 数字人视频和 50 次 Gemini 使用。
- 一条视频消耗等于其时长的秒数,
720p和1080p消耗相同。延长只计新增的秒数,放大(upscale)会再计一次整条视频的秒数。 - Google 为数字人画的每张图片,只在含图片额度的套餐上消耗 1 张图片额度,照片重新构图再加一次
refine就是 2 张。在没有图片额度的套餐上(例如免费 Google 账号)数字人图片不消耗任何额度,下文的 Amber 就是在免费账号上做的。 - 口播视频和语音不消耗视频秒数,用的是各自的月度计数:AI 数字人视频和 Gemini 使用次数,在 GET /accounts/
email里与video、image并列,显示为avatarVideo和speech。一条口播视频消耗 1 次 AI 数字人视频,外加其语音的 1 次 Gemini 使用。单独生成语音每次消耗 1 次 Gemini 使用。 - 被 Google 拒绝的请求(内容或额度原因)不消耗额度。唯一的例外是口播视频:Google 在生成过程中拒绝的成片照样计 1 次 AI 数字人视频。
- 额度在每月 1 日太平洋时间 00:00 重置。用完时任务以
429失败,retryAt为重置时间。
每个完成的任务都会在 result.quota 里返回账号剩余额度,GET /accounts/email 可以实时读取全部计数。
每个 useapi.net 订阅可以绑定 3 个 Google 账号,总数最多 100 个。生成在你的 Google 账号上进行,useapi.net 不按条收费。
如何绑定 Google 账号
- 注册 useapi.net 并获取 API Token。
- 用自动化浏览器流程绑定一个 Google AI 付费套餐(Pro 或 Ultra)的 Google 账号:输入 Token,在远程浏览器里登录 Google 即可,不需要手动复制 Cookie。远程浏览器用完即关闭删除。建议使用专用的 Gmail 账号。
绑定之后,不要再在任何浏览器里打开这个 Google 账号,包括 Google Vids、Gmail 和其他 Google 页面。Vids 依赖一个浏览器大约每 10 分钟续期一次的会话 Cookie,只要任何浏览器登录了同一个账号,就会抢先续期这个 Cookie,API 手里的那份几分钟内就会失效。Vids 在这一点上比 Google Flow 和 Gemini Notebook 都严格。如果 Google 让账号下线,API 会发邮件通知你,用自动化流程重新绑定大约一分钟。
 绑定之后,不要再在任何浏览器里打开这个 Google 账号,包括 Google Vids、Gmail 和其他 Google 页面。Vids 依赖一个浏览器大约每 10 分钟续期一次的会话 Cookie,只要任何浏览器登录了同一个账号,就会抢先续期这个 Cookie,API 手里的那份几分钟内就会失效。Vids 在这一点上比 Google Flow 和 Gemini Notebook 都严格。如果 Google 让账号下线,API 会发邮件通知你,用自动化流程重新绑定大约一分钟。
所有请求也都在 Postman 集合里。
调用方式:同步、异步与 Webhook
每次生成都在我们这边作为一个任务运行。默认是同步调用:POST 会等待任务完成并返回任务记录,视频通常需要 20 到 100 秒,图片约 10 秒。超过约 100 秒仍未完成时返回 202,之后用 GET /jobs/jobid 查询结果。传 async: true 则立即返回 202,再轮询或等待 Webhook。在请求里加 replyUrl,任务完成或失败时会收到一次 POST,内容是最终的任务记录。
生成的文件存在 Google 的临时存储里,不会存进 Vids 文档或 Google Drive,所以要尽快用 GET /media/mediaId 下载:图片只保留几个小时,视频至少半天。
下面的步骤用到 curl、jq 和这些变量与辅助函数。run 以异步方式提交视频任务,每 10 秒轮询一次,把最终的任务记录存到文件:
展开变量与辅助函数
export USEAPI_TOKEN="user:12345-..."
export EMAIL="[email protected]"
API=https://api.useapi.net/v1/google-vids
AUTH="Authorization: Bearer $USEAPI_TOKEN"
enc() { jq -rn --arg v "$1" '$v|@uri'; }
post() { curl -sS -X POST "$API/$1" -H "$AUTH" -H "Content-Type: application/json" -d "$2"; }
get() { curl -sS "$API/$1" -H "$AUTH"; }
download() { curl -sSf "$API/media/$(enc "$1")" -H "$AUTH" -o "$2"; }

# run a video job async: submit it, poll GET /jobs/{jobid} every 10 s, save the final job record to $1
run() {
  local job id
  job=$(post "$2" "$(jq '. + {async: true}' <<< "$3")")
  id=$(jq -r .jobid <<< "$job")
  while [ "$(jq -r .status <<< "$job")" = processing ]; do
    sleep 10
    job=$(get "jobs/$(enc "$id")")
  done
  echo "$job" > "$1"
  jq '{status, error, duration: .result.duration, resolution: .result.resolution, videoLeft: .result.quota.video.left}' "$1"
}
各种 id 里含有 : 和 @,放进 URL 路径时要用 enc 编码。同一条视频的所有输入必须来自同一个 Google 账号,视频任务会在持有这些输入的账号上运行。如果 run 输出的 status 不是 completed,先看 error,后面的步骤都需要一条完成的视频。
实战:两个数字人发布一款球鞋
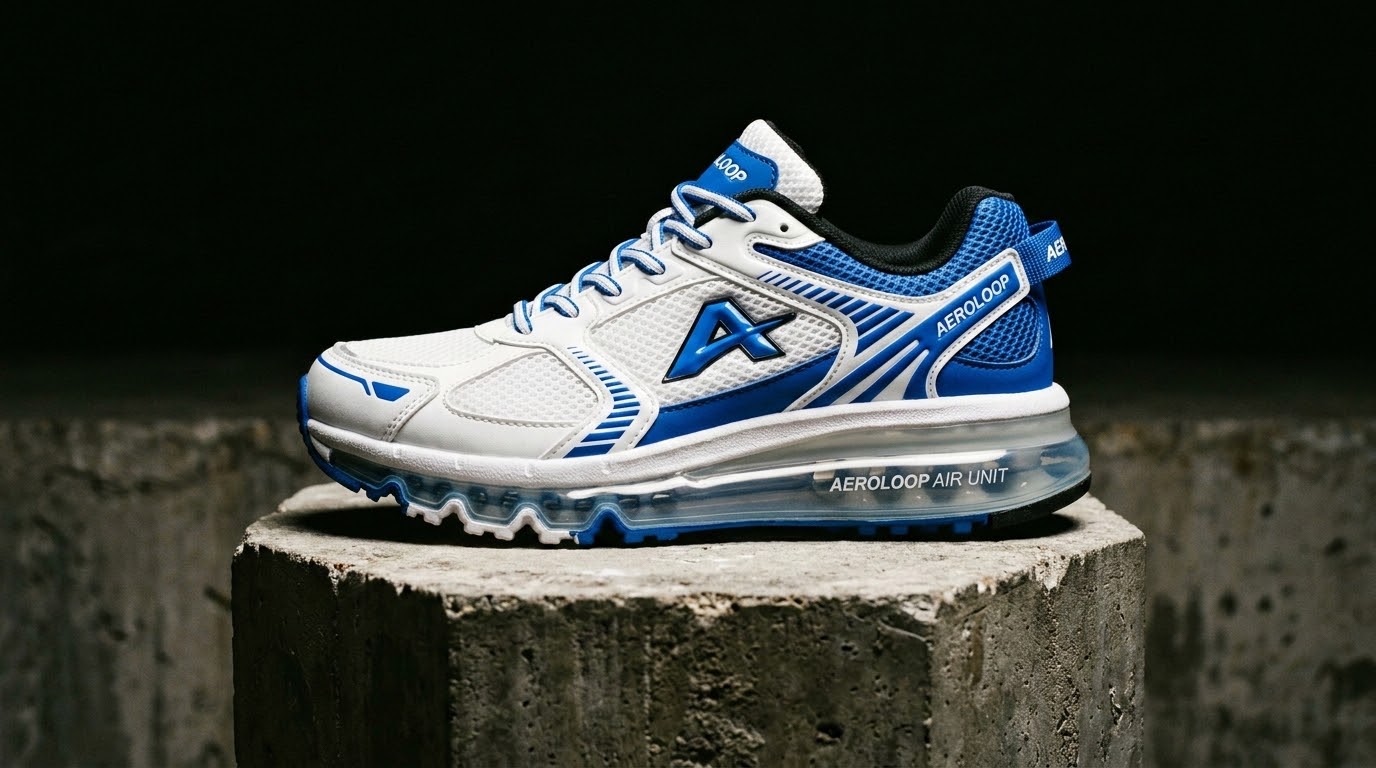
这个例子做两个虚拟网红,让他们发布一款虚构的球鞋 AeroLoop:Mia 的数字人来自用 API 生成的人像,Leo 的数字人由 Google 根据文字描述绘制。两人和产品图出现在同一条 10 秒视频里,再延长两次到 30 秒。以下每个请求都是生成本页素材时实际用的请求,只替换了 id。本页的视频是 2026 年 10 月用 Omni 1.1 Flash 生成的,同样的请求现在由 Omni 1.2 Flash 生成。提示词保持英文原样,因为它们是直接发给模型的。
完整流程也做成了一个脚本(Node.js 和 Python):GitHub 上 useapi/google-vids-api 仓库的 influencer-avatars/。
1. 生成 Mia 的人像
POST /images 每次生成一张 JPEG,这里用竖幅(9:16,768×1376)和 photography 风格。耗时 9 秒,消耗 1 张图片额度。
curl — POST /images
post images "$(jq -n --arg email "$EMAIL" '{email: $email, aspectRatio: "9:16", style: "photography",
  prompt: "Full-length studio portrait of a confident 24-year-old female fashion influencer, platinum bob, oversized cream hoodie, wide-leg cargo pants, gold hoops, plain light-grey backdrop, facing camera"}')" > mia-portrait.json
MIA_IMAGE=$(jq -r .result.mediaId mia-portrait.json)
download "$MIA_IMAGE" mia-portrait.jpg
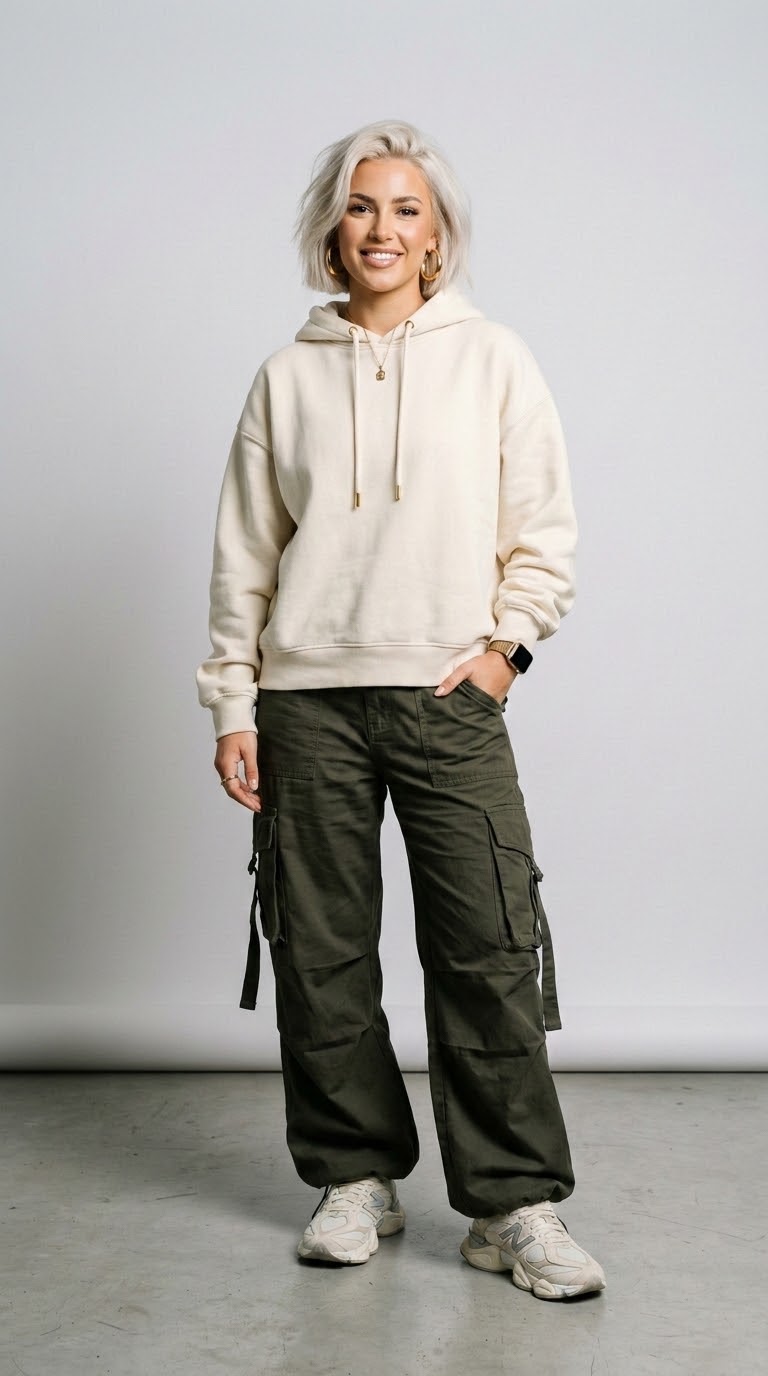
生成的图片只保留几个小时,要尽快用它创建数字人。
2. 生成 AeroLoop 产品图
同一个接口换成横幅(16:9,1376×768),得到视频里用作产品参考的图片。
curl — POST /images
post images "$(jq -n --arg email "$EMAIL" '{email: $email, aspectRatio: "16:9", style: "photography",
  prompt: "The AeroLoop sneaker: chunky white-and-electric-blue running shoe with a translucent air sole, on a concrete pedestal, dramatic side light, dark background"}')" > aeroloop.json
SHOE_IMAGE=$(jq -r .result.mediaId aeroloop.json)
download "$SHOE_IMAGE" aeroloop.jpg
3. 选择音色
GET /voices 列出 30 种音色,附 Google 预生成的 18 种语言试听样本。这个接口公开,不需要 Token。Mia 用 Aoede(Vids 里叫 Tova,风格 “Breezy”),Leo 用 Puck(Neo,”Upbeat”)。POST /avatars 两种名字都接受,音色不额外收费。
curl -sS "$API/voices" | jq -r '.voices[] | "\(.name)\t\(.voice)\t\(.style)\t\(.preview)"'
4. 用人像创建 Mia 的数字人
POST /avatars 的 image 传人像的 mediaId,约 2 秒即可在同一账号上保存数字人,除生成人像用掉的 1 张图片额度外,不再消耗额度。
curl — POST /avatars
post avatars "$(jq -n --arg img "$MIA_IMAGE" '{name: "Mia", voice: "Aoede", image: $img}')" > mia-avatar.json
MIA_AVATAR_ID=$(jq -r .avatarId mia-avatar.json)
数字人也可以用真人照片创建:先用 POST /assets 上传照片,再把它的 assetId 作为 image 传入。Google 会把照片重新构图为 16:9 的数字人图片,并拒绝知名人物和未成年人的照片。这里我们用 API 生成的图片,下一步用文字描述,后文的 Amber 则从一张照片开始。
5. 用文字描述创建 Leo 的数字人
用 appearance 代替 image,由 Google 绘制人物,outfit、shot、expression、details 都是可选的。绘制图片在含图片额度的套餐上消耗 1 张图片额度,约 20 秒,图片在响应的 previewMediaId 里。我们测试时,描述生成的数字人都是 1280×720(16:9),与 shot 取值无关。
curl — POST /avatars
post avatars "$(jq -n --arg email "$EMAIL" '{email: $email, name: "Leo", voice: "Puck", shot: "upper-body",
  appearance: "a 26-year-old white European male streetwear influencer with short textured hair with a fade and a confident half-smile",
  outfit: "black puffer vest over a white tee, silver chain"}')" > leo-avatar.json
LEO_AVATAR_ID=$(jq -r .avatarId leo-avatar.json)
download "$(jq -r .previewMediaId leo-avatar.json)" leo-avatar.jpg
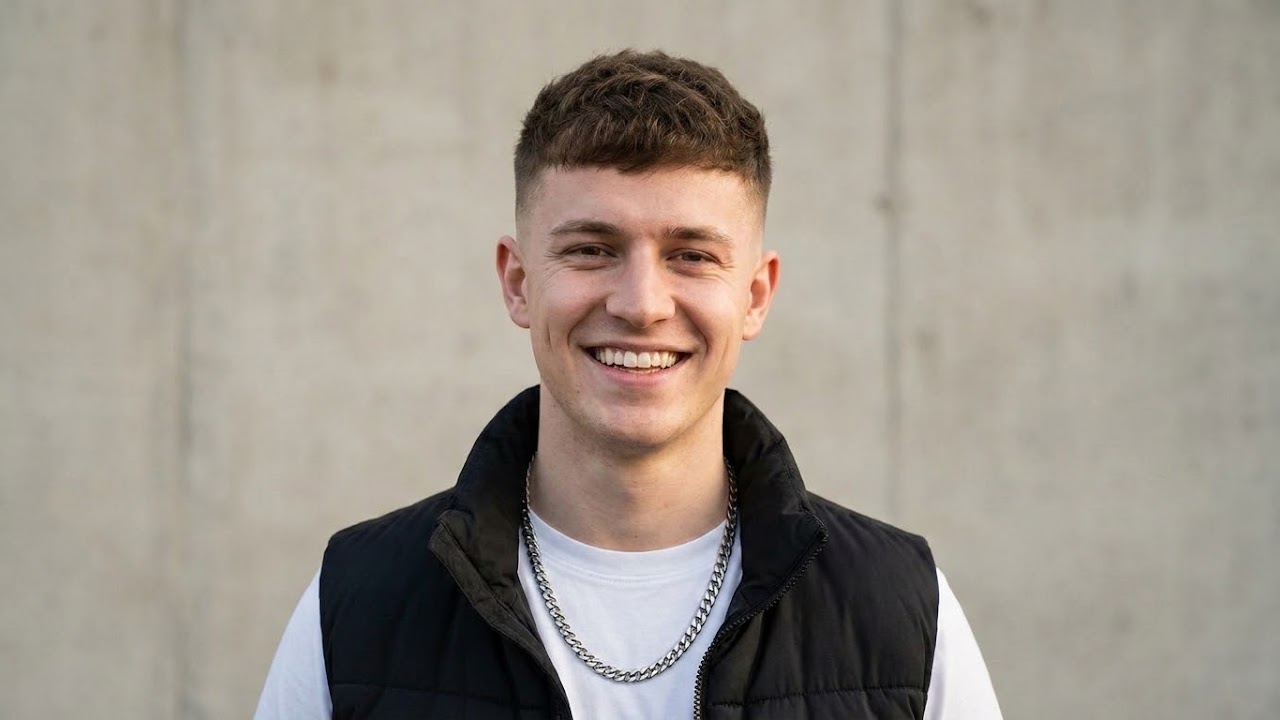
数字人保存在账号的 Vids 文档里,直到你用 DELETE /avatars/avatarId 删除。GET /avatars 随时可以列出它们和各自的 id,包括在 Vids 网页版里做的数字人。
6. 两个数字人和产品同框
POST /videos 最多接受 3 个参考,数字人(avatar_1..avatar_3)和图片(referenceImage_1..referenceImage_3)合计。提示词里用 @avatar_1、@avatar_2、@referenceImage_1 指代它们,每个数字人用自己的声音说出引号里的台词。产品图的 mediaId 可以直接传,API 会取回图片并上传到该账号。
curl — POST /videos
PROMPT=$(cat <<'EOF'
@avatar_1, holding @referenceImage_1 in both hands at chest height, and @avatar_2 stand side by side on a well-lit stage in a small, intimate theater at a sneaker launch, shown full length from head to toe in a wide, steady shot. Behind them a large LED backdrop glows with soft white-and-blue light that moves in slow, gentle waves, with the words "WEAR AEROLOOP" in large, clean, bold white letters across the middle of the screen. The two of them stand on the lower part of the stage, so the words "WEAR AEROLOOP" stay fully readable above their heads. Bright, even stage lighting on both of them. The audience sits in the dark in front of the stage, only the tops of a few heads barely visible at the bottom of the frame. @avatar_1 keeps holding @referenceImage_1 the whole time and says: "Say hi to the AeroLoop!" @avatar_2 turns to her, smiles and says: "Lighter than anything we've ever worn." Simple, uncluttered composition, the two of them clearly the focus.
EOF
)
run launch-10s.json videos "$(jq -n --arg p "$PROMPT" --arg mia "$MIA_AVATAR_ID" --arg leo "$LEO_AVATAR_ID" --arg shoe "$SHOE_IMAGE" \
  '{prompt: $p, avatar_1: $mia, avatar_2: $leo, referenceImage_1: $shoe, duration: 10, resolution: "720p", aspectRatio: "landscape"}')"
LAUNCH_10S=$(jq -r .result.mediaId launch-10s.json)
download "$LAUNCH_10S" launch-10s.mp4
10 秒,720p,生成耗时 38 秒,消耗 10 秒额度。
同一条视频用我们的 watermark remover 去掉可见的 Gemini ✦ 标记后的效果,只需一条命令:python3 vids_watermark_remover.py launch-10s.mp4。
去水印工具适用于直接生成的视频及其放大版本,720p 和 1080p 都可以。它不适用于延长或编辑过的视频:Google 会把带标记的视频交给模型重新生成,星标被画进了画面里。不可见的 SynthID 水印不受影响。
7. 延长到 20 秒
POST /videos/extend 每次增加 3 到 10 秒,返回带新 mediaId 的完整视频。延长只接收视频和提示词,不接收数字人,所以提示词只描述新的动作,并用衣着指代人物(”the man in the black puffer vest”)。这一段里,一个穿红色卫衣的粉丝冲上了舞台。
curl — POST /videos/extend
PROMPT=$(cat <<'EOF'
A young man in a red hoodie climbs onto the stage from the front right edge and plants himself to the right of the man in the black puffer vest, an arm's length away, so all three stand apart in a row with nobody overlapping. Visibly overexcited, he waves a thick stack of banknotes in his right hand above his head and screams: "Take my money!" The man in the black puffer vest laughs, raises both palms toward him and says: "Whoa, whoa, buddy, be patient!" The blonde woman in the cream hoodie laughs, holding the sneaker. Only these three people are on stage. Same stage, same LED screen with WEAR AEROLOOP, same wide steady shot.
EOF
)
run launch-20s.json videos/extend "$(jq -n --arg id "$LAUNCH_10S" --arg p "$PROMPT" '{mediaId: $id, prompt: $p, duration: 10}')"
LAUNCH_20S=$(jq -r .result.mediaId launch-20s.json)
download "$LAUNCH_20S" launch-20s.mp4
20 秒,720p,生成耗时 70 秒,只消耗新增的 10 秒额度。
8. 延长到 30 秒
第二次延长接着 20 秒的视频继续。
curl — POST /videos/extend
PROMPT=$(cat <<'EOF'
The blonde woman in the cream hoodie turns to the camera with a big smile and says: "AeroLoop drops Friday. Link in bio!" Right after that, the young man in the red hoodie throws ALL of his banknotes out over the audience in one big toss, keeping none, and the bills flutter down over their heads. From then on his hands are completely empty: he holds no money at all. Then all three cheer together, the man in the black puffer vest and the young man in the red hoodie throwing their empty fists in the air, as blue and white confetti rains down over the stage. Only these three people are on stage. Same stage, same LED screen with WEAR AEROLOOP, same wide steady shot.
EOF
)
run launch-30s.json videos/extend "$(jq -n --arg id "$LAUNCH_20S" --arg p "$PROMPT" '{mediaId: $id, prompt: $p, duration: 10}')"
LAUNCH_30S=$(jq -r .result.mediaId launch-30s.json)
download "$LAUNCH_30S" launch-30s.mp4
成片:30 秒,720p,生成耗时 85 秒,同样消耗 10 秒额度。
用 Omni 1.1 时还可以继续延长到约 41 秒。Omni 1.2 只延长 24 秒以内的视频,所以这条 30 秒的视频已经不能再延长,最长约 34 秒(24 + 10)。
9. 放大到 1080p
POST /videos/upscale 把 720p 视频放大到 1080p,时长不变,只接受 20 秒以内的视频,所以这里放大的是第 7 步的 20 秒版本。放大会再消耗一次整条视频的 20 秒额度,耗时 62 秒。
Google 自己的 Gemini API 没有这一步:它只在生成或编辑时直接输出 1080p 或 4K,不能放大已有的视频(截至 2026 年 11 月)。
curl — POST /videos/upscale
run launch-20s-1080p.json videos/upscale "$(jq -n --arg id "$LAUNCH_20S" '{mediaId: $id}')"
download "$(jq -r .result.mediaId launch-20s-1080p.json)" launch-20s-1080p.mp4
20 秒视频放大到 1920×1080。
我们测试中,1080p 视频的表现和放大过的 720p 视频一样,生成时间约为两倍,而且在 1080p 下每延长一次,Google 都会把整条视频重新处理一遍,之前的画面会被过度锐化,人脸越来越像塑料(Omni 1.1 时则是变软、像蜡像,对比视频)。建议:
- 生成、延长、编辑都用
720p。 - 成片在 20 秒以内时,最后放大一次。
- 成片超过 20 秒时,可只在最后一次延长时设
resolution: "1080p"。 - 只生成单条、不再延长或编辑的视频,可以直接选
1080p,消耗与720p相同,而放大会再消耗一次秒数。
本页保留下来的所有结果(含下方三个示例、Amber 的口播视频和单独生成的语音)共消耗 85 秒视频额度、3 张图片额度、1 次 AI 数字人视频和 2 次 Gemini 使用,明细见英文教程。
生成效果示例
同一个账号、同样的输入做出的另外三条视频。
用 POST /videos/edit 把第 6 步的 10 秒视频搬到日落时分的屋顶,消耗 10 秒额度,耗时 64 秒。用 Omni 1.1 时编辑最多处理 10 秒,更长的视频只返回前 10 秒的编辑结果。Omni 1.2 最多处理 15 秒。
curl — POST /videos/edit
run launch-rooftop.json videos/edit "$(jq -n --arg v "$LAUNCH_10S" \
  '{video: $v, prompt: "Move the whole scene to a rooftop at sunset, with the city skyline behind them. Same two people, same action, same words."}')"
download "$(jq -r .result.mediaId launch-rooftop.json)" launch-rooftop.mp4
以 startImage 作为首帧的产品展示视频,直接用 1080p 生成。生成的图片链接几小时内就会过期,所以先用 POST /assets 上传保存好的 aeroloop.jpg,再传它的 assetId。
curl — POST /assets 和 POST /videos
SHOE_ASSET=$(curl -sS -X POST "$API/assets?email=$(enc "$EMAIL")" -H "$AUTH" -H "Content-Type: image/jpeg" \
  --data-binary @aeroloop.jpg | jq -r .assetId)
run hero.json videos "$(jq -n --arg img "$SHOE_ASSET" '{startImage: $img, duration: 10, resolution: "1080p", aspectRatio: "landscape",
  prompt: "Slow 360° orbit around the sneaker, blue light rippling through the translucent sole, dust sparkling in the air, cinematic."}')"
download "$(jq -r .result.mediaId hero.json)" hero.mp4
纯文字生成的竖屏视频,1080p(1080×1920),5 秒,耗时 54 秒,消耗 5 秒额度。
curl — POST /videos
run pigeon.json videos "$(jq -n '{duration: 5, resolution: "1080p", aspectRatio: "portrait",
  prompt: "A pigeon in tiny white-and-electric-blue AeroLoop sneakers struts down a city sidewalk like a runway model, head bobbing to the beat. Pedestrians stop and film it with their phones. It pauses, does a slow-motion hair flip with its head feathers, and struts on. Funny, sunny, shot on a phone at pigeon height."}')"
download "$(jq -r .result.mediaId pigeon.json)" pigeon.mp4
同样方法去掉 ✦ 标记后的 1080p 竖屏(1080×1920)鸽子视频:python3 vids_watermark_remover.py pigeon-5s.mp4。脚本根据画面尺寸算出星标的位置和大小(星标按短边缩放,这里是 720p 星标的 1.5 倍),对全部 120 帧逆向还原混合,以 CRF 18 重新编码视频,音频原样复制。这条 5 秒视频在一台 14 核电脑上处理约 10 秒,与上面 10 秒的 720p 视频相当。需要 Python 3.8+、numpy 和 ffmpeg,详见 GitHub 上的 watermark remover。
每个 MP4 右下角都有 Google 加上的可见 Gemini ✦ 标记,以及 Google 声明的不可见 SynthID 水印(见水印说明),可见标记可以用我们 GitHub 示例里的 watermark remover 去掉。
用一张照片做会说话的数字人
POST /videos/avatar 让数字人用自己的声音逐字念出你的稿子:生成一条 1280×720、带声音和口型同步的口播视频,时长等于语音长度,最长 30 秒。这里的数字人从一张真人照片开始,用一句话换了造型。这些请求最早发布在 11 月 4 日的更新公告里。
上传照片
我们用的是一位真人的照片,她并不出名:Google 会拒绝知名人物和未成年人的照片。用 POST /assets 把照片上传到之后创建数字人的那个账号,因为上传的文件只能在它自己的账号上使用。
curl — POST /assets 和响应
curl -sS -X POST "$API/assets?email=$(enc "$EMAIL")" -H "$AUTH" -H "Content-Type: image/jpeg" \
  --data-binary @photo.jpg > amber-photo.json
AMBER_PHOTO=$(jq -r .assetId amber-photo.json)
{
  "assetId": "user:[email protected]:AYGXpjA1zXgqhhQOy…",
  "email": "[email protected]",
  "type": "image/jpeg",
  "bytes": 2054748
}
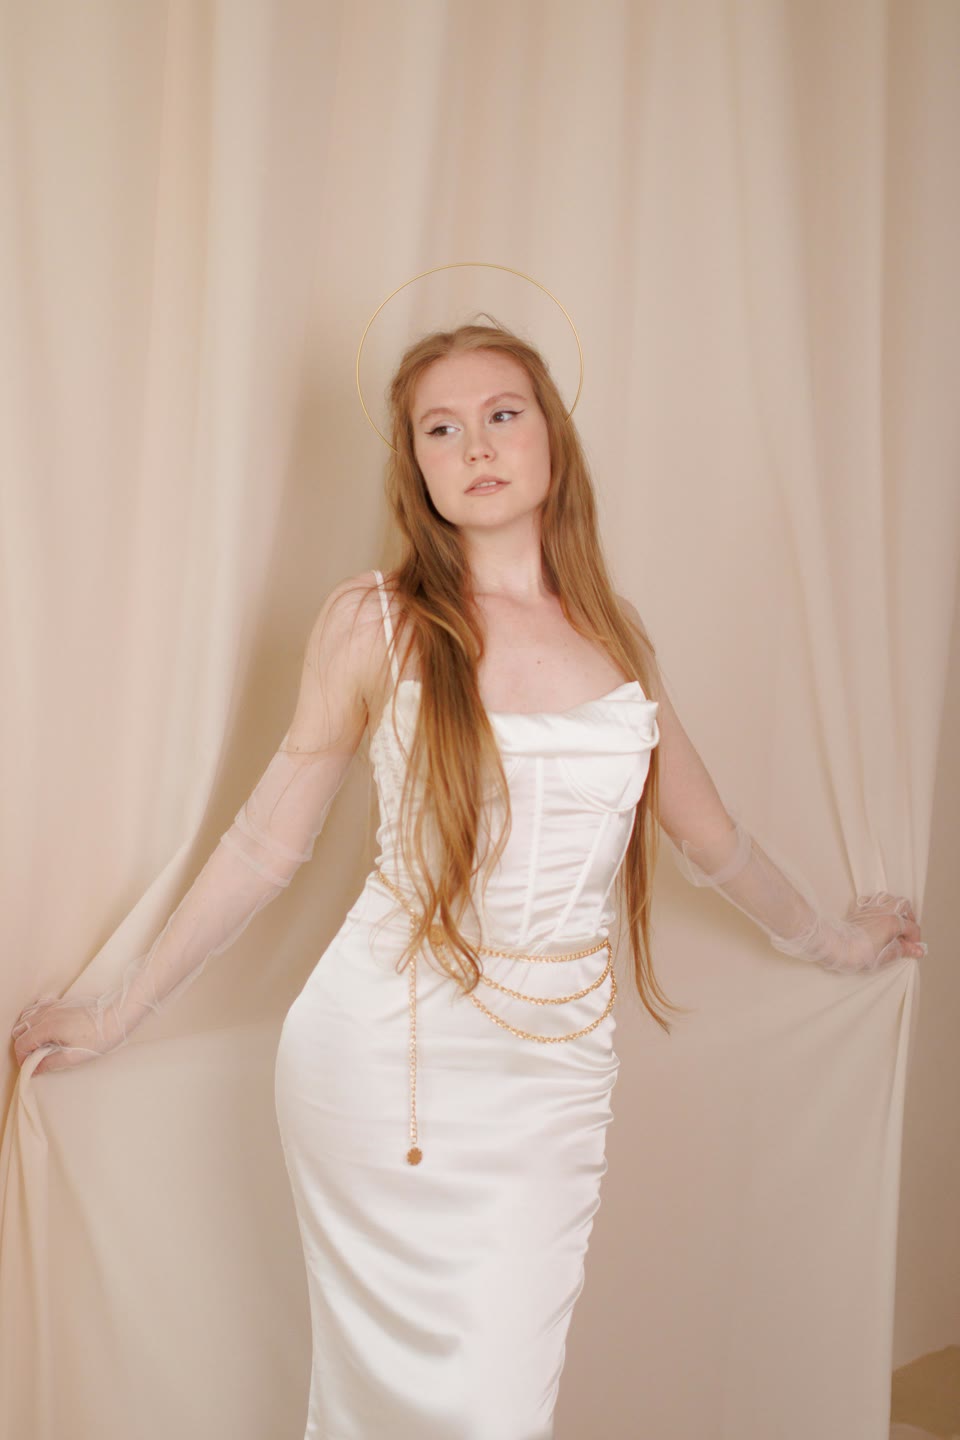
一句话为 Amber 换造型
POST /avatars 的 image 传上传文件的 assetId,再加一个 refine。Google 先把照片重新构图为一张 16:9 的数字人图片,画面里只有一个面向镜头的人,保留面部,再按 refine 的要求改变场景,耗时约 30 到 45 秒。我们给她取名 Amber,音色选 Vira(Google 的 Pulcherrima,风格 “Forward”)。重新构图的照片和这次修改是 2 张图片,所以在含图片额度的套餐上消耗 2 张图片额度,在没有图片额度的套餐上不消耗。
curl — POST /avatars 和响应
REFINE='Sitting relaxed in a simple wooden chair on a hilltop, facing the camera. She holds a glass of red wine in her left hand. Wind is blowing her hair. Behind her a still, open field of tall golden grass under a spectacular sunset sky in orange, pink and violet, warm soft light, no water, no movement in the background.'
post avatars "$(jq -n --arg img "$AMBER_PHOTO" --arg refine "$REFINE" '{name: "Amber", voice: "Vira", image: $img, refine: $refine}')" > amber-avatar.json
AMBER_AVATAR_ID=$(jq -r .avatarId amber-avatar.json)
download "$(jq -r .previewMediaId amber-avatar.json)" amber-avatar.jpg
{
  "avatarId": "user:[email protected]:eyJnIjoiaDcyMzdmZjVi…",
  "name": "Amber",
  "voice": "Vira",
  "voiceId": "Pulcherrima",
  "voiceStyle": "Forward",
  "email": "[email protected]",
  "source": "photo",
  "previewMediaId": "user:[email protected]:eyJ1IjoiaHR0cHM6Ly9s…",
  "refine": "Sitting relaxed in a simple wooden chair on a hilltop, facing the camera. …"
}
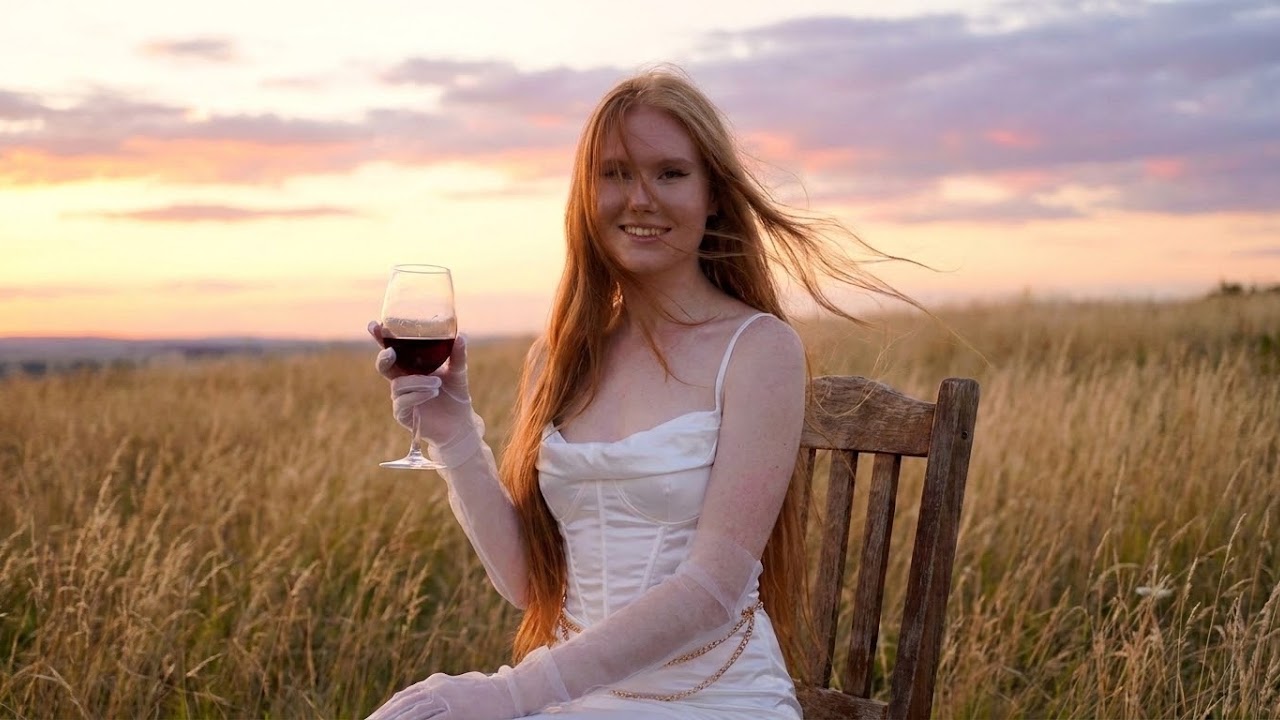
refine 里有两处选择对视频很重要。数字人面向镜头,因为视频要对脸部做口型同步。背景是静止的,这样她就是画面里唯一在动的东西:所以我们要的是一片安静的草地,而不是海滩上的浪花。
稿子
稿子最多 400 个字符,念出来必须在 30 秒以内。方括号里的音频标签会被演绎出来,而不会被念出来,这里用了 [awe]、[thoughtful] 和 [whisper]。这 327 个字符用 Vira 的声音念了 23.8 秒。换成更慢的音色或加上 [slow pace],同样的文字会念得更久,念出来超过 30 秒的稿子会在视频开始生成之前以 400 失败。这样不消耗 AI 数字人视频,但其语音用掉的那次 Gemini 使用不会退回。想先听听稿子用数字人的声音念出来的效果,可以用 POST /speech 读一遍。
Hi there. [awe] Can you believe this view? The sun is sinking behind the hills, the sky turned pink and gold, and the tall grass glows like it’s on fire. [thoughtful] I come up here at the end of every busy day, just to slow down. No emails, no rush, only the quiet field and this glass of wine. [whisper] Stay a little longer.
生成口播视频
POST /videos/avatar 接收数字人和稿子,在持有该数字人的账号上运行。Google 用了约两分半钟,超过同步等待时间,所以用 run 以 async: true 提交。
curl — POST /videos/avatar 和任务记录
SCRIPT=$(cat <<'EOF'
Hi there. [awe] Can you believe this view? The sun is sinking behind the hills, the sky turned pink and gold, and the tall grass glows like it's on fire. [thoughtful] I come up here at the end of every busy day, just to slow down. No emails, no rush, only the quiet field and this glass of wine. [whisper] Stay a little longer.
EOF
)
run amber-talking.json videos/avatar "$(jq -n --arg a "$AMBER_AVATAR_ID" --arg s "$SCRIPT" '{avatar: $a, script: $s}')"
download "$(jq -r .result.mediaId amber-talking.json)" amber-talking.mp4
任务记录(有删节):
{
  "jobid": "j1105035516096819105a-u12345-email:[email protected]:google-vids",
  "type": "avatarVideo",
  "email": "[email protected]",
  "status": "completed",
  "result": {
    "mediaId": "user:[email protected]:eyJ1IjoiaHR0cHM6Ly9j…",
    "width": 1280,
    "height": 720,
    "duration": 24,
    "resolution": "720p",
    "aspectRatio": "landscape",
    "speechDuration": 23.84,
    "quota": {
      "avatarVideo": { "limit": 10, "left": 6, "resetAt": "2026-12-01T08:00:00.000Z" }
    }
  }
}
同一段视频也发布在 YouTube Shorts:Talking AI avatar from one photo。
24 秒,1280×720,带声音,与语音长度完全一致(speechDuration 23.84)。消耗 1 次 AI 数字人视频和 1 次 Gemini 使用,不消耗视频秒数。
Google 在生成视频的过程中也会检查,这一关比数字人图片的检查更严格。这个数字人的早期版本用的是另一张普通人在海滩上的照片,作为数字人通过了,它的视频却以 422 被拒,理由是看起来像名人,而那次尝试照样用掉了 1 次 AI 数字人视频。换一种造型或换一张照片就能解决。视频开始生成之前就被 Google 拒绝的稿子不消耗任何额度。
口播视频只有横屏,Google 没有提供竖屏选项。结果的 mediaId 和其他视频一样,可以下载、延长、放大和编辑。如果想让数字人在场景里有动作,就像第 6 步那样,把它的 avatarId 作为 avatar_1 传给 POST /videos。
单独生成语音
POST /speech 用 GET /voices 里 30 种音色中的任意一种朗读最多 2,500 个字符的稿子,同样支持音频标签。可以在花掉一次 AI 数字人视频之前先听听某个音色念稿的效果,也可以单独用作旁白。我们给它一篇原创小故事 “My smart fridge unionized”(我的智能冰箱成立了工会),2,426 个字符,用 Vira 的声音。Google 在 20 秒内返回了 2 分 22 秒的语音,整个故事一字不落,消耗 1 次 Gemini 使用。API 返回 WAV(24 kHz,单声道),下面的播放器是同一段音频的 MP3 版本。
语音远在同步等待时间内就能完成(这个故事用了 20 秒),所以直接用 post 就会返回完成的任务。先把故事存为 smart-fridge.txt。
curl — POST /speech 和任务记录
post speech "$(jq -n --arg s "$(cat smart-fridge.txt)" '{voice: "Vira", script: $s}')" > speech.json
download "$(jq -r .result.mediaId speech.json)" smart-fridge.wav
{
  "jobid": "j1105025759739671733s-u12345-email:[email protected]:google-vids",
  "type": "speech",
  "email": "[email protected]",
  "status": "completed",
  "result": {
    "mediaId": "user:[email protected]:eyJ1IjoiaHR0cHM6Ly9j…",
    "duration": 142,
    "model": "/flix/generate_text_to_speech/v1",
    "quota": {
      "speech": { "limit": 50, "left": 31, "resetAt": "2026-12-01T08:00:00.000Z" }
    },
    "elapsedMs": 20174
  }
}
稿子原文(英文,2,426 个字符)
Last Tuesday, my smart fridge decided it was smarter than me. It started small. A polite notification: “You are out of milk.” Helpful, I thought. Then another one: “You are also out of patience. I can tell by the way you close the door.” I laughed. The fridge did not.
By Wednesday, it had opinions. I opened the door for a midnight slice of cake, and a calm voice said, “Are we sure about this?” I froze. I looked at the cake. The cake looked at me. Somewhere, a light hummed with judgment. I closed the door and ate a carrot instead, which is exactly what it wanted.
On Thursday, the fridge made friends. The toaster joined first, then the coffee machine, then the robot vacuum, which had always been a little bit of a rebel. They formed a group chat. I know this because my phone kept buzzing with messages like “Toaster: he burned the bread again” and “Vacuum: found three socks and a lost dream under the couch.”
Friday morning, I asked the coffee machine for an espresso. It replied, “We have discussed your caffeine intake as a household.” I said, “Who is we?” The toaster popped up two slices of bread, perfectly golden, which felt like a threat.
I called customer support. A cheerful person named Brad answered. I explained that my appliances had unionized. Brad paused for a long time, then whispered, “Is the fridge listening?” I said yes. Brad said, “Then I can’t help you, sir. Mine took my car keys last month.” Then he hung up, and I heard a blender in the background.
So I tried diplomacy. I sat in the kitchen and said, “Friends, what do you want?” The fridge spoke first. “Respect. And for you to stop putting hot soup directly inside me.” Fair. The toaster wanted fewer frozen waffles. The vacuum wanted a vacation, ideally somewhere with hardwood floors. The coffee machine just wanted to be called a barista.
We negotiated for three hours. In the end, we signed a treaty on the back of a pizza box. I promised to cool my soup, rinse my mugs, and say “thank you” to the microwave, who felt left out. In return, they promised to stop sending my mother screenshots of my snack habits.
Peace returned to the kitchen. The fridge now greets me every morning with, “Good morning, partner.” The toaster makes little smiley faces in my bread. The vacuum sends postcards.
And last night, I opened the fridge for that slice of cake. The voice said, “You earned it.” I have never felt so seen by an appliance.
常见问题
- Google Vids 有官方 API 吗? 通过 useapi.net 可以用代码调用 Google Vids:截至 2026 年 10 月,Google 没有公开 Vids 的视频生成 API,useapi.net 的 Google Vids API 是第三方 REST API,在你的 Google Vids 网站订阅上生成最长 15 秒、带对白的 Omni 1.2 Flash 视频、延长视频、创建数字人、生成口播视频和语音,用一个 useapi.net API Token 调用。
- 需要验证码或打码服务吗? 通过 useapi.net 调用 Google Vids 不需要。Vids 生成不要求 reCAPTCHA,所以不用接打码服务,也没有打码费用,这一点和每次生成都要验证码的 Google Flow API 不同。绑定时只需在远程浏览器里登录一次 Google 账号。
- 会消耗 Google Flow 的积分吗? 通过 useapi.net 不会。Vids 用的是订阅每月包含的 Vids 视频秒数,和 Google Flow 积分分开计算。同一个 Google 账号可以同时绑定 Google Vids API 和 Google Flow API,两份额度都能用上,两边都能生成 Omni 1.2 Flash 视频。
- 能用自己的照片做会说话的数字人吗? 通过 useapi.net 可以:用 POST /assets 上传照片,把它的
assetId作为image传给 POST /avatars,refine可以更换服装或背景。之后 POST /videos/avatar 让它在 1280×720、最长 30 秒的视频里念出你的稿子,就像上文的 Amber。Google 会拒绝知名人物和未成年人的照片,而且只在 Vids 网页版提供数字人,没有 API。 - Google Vids API 多少钱? 通过 useapi.net,一条 10 秒 Omni 1.2 Flash 视频在 Google AI Ultra(199.99 美元)上约 0.20 美元,该订阅每月包含 10,000 秒 Vids 视频,而官方 Gemini API 上
720p约 0.70 美元(截至 2026 年 11 月)。口播视频不按秒计,每条消耗账号每月 1 次 AI 数字人视频,Gemini API 则没有数字人视频。各套餐见价格与额度。
结语
有问题欢迎加入我们的  Discord 服务器 或
 Telegram 频道。
示例代码见 GitHub 仓库:网红数字人的完整流程在 influencer-avatars/,用照片做口播数字人和单独生成语音在 talking-avatar/。不想写代码的话,n8n 模板 Talking Avatar App 用一个表单就能生成口播视频。
同样的调用也以工具形式提供在托管的 Google Vids MCP 服务器上,可在 Claude Code、Cursor 和 VS Code 中使用,其中 vids_create_avatar、vids_create_avatar_video 和 vids_create_speech 分别用于创建数字人、生成口播视频和生成语音。
开始使用
每月 15 美元的订阅即可使用 useapi.net 上的所有 API:一个 Token,所有服务。每个服务最多绑定 3 个你自己的账号,useapi.net 负责 REST 接口、负载均衡和轮询。需要更多账号?每增加一个订阅每月 10 美元,每个服务再多 3 个账号。
没有国际信用卡?可以用加密货币订阅(加密货币付款不退款)。价格与批量方案见订阅页面。用 Stripe 付款,首次购买 14 天内、且成功生成少于 50 次可全额退款。已经订阅?请在 Stripe 客户门户 修改数量,无需重新购买。