How to Make AI Influencer Videos with Avatars via the Google Vids API
15 min read • October 7, 2026 (November 6, 2026)
Table of contents
- Introduction
- What it cost
- Before you start
- How it was built
- Examples
- A talking avatar from a photo
- Speech on its own
- What we learned
- Frequently asked questions
- Conclusion
Introduction
The useapi.net Google Vids API makes talking AI influencer videos from avatars: save a picture and one of 30 Gemini voices once with POST /avatars, then pass the avatar’s id to any Gemini Omni 1.2 Flash video of up to 15 seconds, where it speaks the lines you write in the prompt, or have it read your own script in a talking-head video of up to 30 seconds.
The API runs on your Google Vids account, with a paid Google AI subscription (Google AI Pro or Ultra). This walkthrough makes two influencers and launches a sneaker with them. Mia’s avatar comes from a portrait made with the API, and Leo’s is drawn by Google from a written description. They present the AeroLoop, a made-up sneaker, on a theater stage in one 10-second clip with both avatars and a product image, and two extends take it to 30 seconds. An edit moves the scene to a rooftop, and two more clips show what the same calls make without avatars. A third avatar, Amber, starts from a photo of a real person, is restyled in one sentence, and reads a 327-character script in a 24-second talking-head video. Last, the same voice reads a 2,426-character story as speech on its own. Every request below is the one that made the media on this page, with the ids replaced and async: true added by the run helper. The clips were made in October 2026 with Omni 1.1 Flash, which Vids replaced with Omni 1.2 Flash on November 5, 2026, and the same requests run on 1.2. Omni 1.2 in Google Vids and Google Flow side by side, with 15-second videos and the price per video: How to Use the Gemini Omni 1.2 Flash API.
The finished 30-second clip at 720p: one 10-second generation and two 10-second extends (steps 6 to 8).
What it cost
useapi.net is an API, not a video service of its own. Every call runs on a Google account you connect through Setup Google Vids, with a paid Google AI subscription, and uses the seconds of video and the images that subscription includes in Google Vids each month. Google AI Ultra $199.99 includes 10,000 seconds of video and 1,000 images a month, and useapi.net adds no per-video charge. Talking avatar videos and speech use no video seconds: they have their own monthly counters, AI avatar videos and Gemini uses, which GET /accounts/email shows as avatarVideo and speech next to video and image. See what each plan includes for the other plans.
What each kept result used, taken from the change in result.quota, and how long each job took (result.elapsedMs):
| Step | Endpoint | Used | Time |
|---|---|---|---|
| Mia’s portrait | POST /images | 1 image | 9 s |
| The AeroLoop product shot | POST /images | 1 image | 9 s |
| Mia’s avatar, from her portrait | POST /avatars | nothing | about 2 s |
| Leo’s avatar, from a description | POST /avatars | 1 image | about 20 s |
| The 10-second launch clip | POST /videos | 10 s | 38 s |
| Extend to 20 seconds | POST /videos/extend | 10 s | 70 s |
| Extend to 30 seconds | POST /videos/extend | 10 s | 85 s |
| Upscale the 20 seconds to 1080p | POST /videos/upscale | 20 s | 62 s |
| Rooftop edit | POST /videos/edit | 10 s | 64 s |
| Edit of the 30-second clip | POST /videos/edit | 10 s | 87 s |
| Product hero clip | POST /videos | 10 s | 62 s |
| The pigeon | POST /videos | 5 s | 54 s |
Amber’s avatar, from a photo with refine | POST /avatars | nothing (made on a plan without images; 2 images on a plan with them) | about 30 to 45 s |
| Amber’s 24-second talking video | POST /videos/avatar | 1 AI avatar video, 1 Gemini use | about 2.5 min |
| The 2,426-character story | POST /speech | 1 Gemini use | 20 s |
| Total | 85 s of video, 3 images, 1 AI avatar video, 2 Gemini uses |
An extend uses only the seconds it adds, not the length of the clip. An upscale uses the clip’s full length again, and an edit uses at most the seconds it edits (with Omni 1.2, a 15-second edit used 10 in our tests). 720p and 1080p cost the same when you generate. A clip you generate again costs its seconds again. Each picture Google makes for an avatar uses 1 image, so a reframed photo plus a refine uses 2. On a plan without images, such as a free Google account, avatar pictures cost nothing: Amber was made on one. A talking avatar video uses 1 AI avatar video, plus 1 Gemini use for its speech, even when Google refuses the finished video. What a video comes to against the official API is in the Google Vids price table.
Before you start
You need a useapi.net API token and a Google account with a paid Google AI subscription, connected through Setup Google Vids. A free Google account gets no Vids video seconds or images: it can still be added, and in our tests (November 2026) it made avatars, talking avatar videos and speech. Every call is also in the Postman collection.
No code: the Talking Avatar App n8n template makes a talking avatar video from a form. The whole pipeline is also on GitHub as one script, in Node.js and Python: influencer-avatars/ in useapi/google-vids-api, and the talking avatar and speech sections as talking-avatar/.
The steps use curl, jq and these variables and helpers:
Expand the variables and helpers
export USEAPI_TOKEN="user:12345-..."
export EMAIL="[email protected]"
API=https://api.useapi.net/v1/google-vids
AUTH="Authorization: Bearer $USEAPI_TOKEN"
enc() { jq -rn --arg v "$1" '$v|@uri'; }
post() { curl -sS -X POST "$API/$1" -H "$AUTH" -H "Content-Type: application/json" -d "$2"; }
get() { curl -sS "$API/$1" -H "$AUTH"; }
download() { curl -sSf "$API/media/$(enc "$1")" -H "$AUTH" -o "$2"; }

# run a video job async: submit it, poll GET /jobs/{jobid} every 10 s, save the final job record to $1
run() {
  local job id
  job=$(post "$2" "$(jq '. + {async: true}' <<< "$3")")
  id=$(jq -r .jobid <<< "$job")
  while [ "$(jq -r .status <<< "$job")" = processing ]; do
    sleep 10
    job=$(get "jobs/$(enc "$id")")
  done
  echo "$job" > "$1"
  jq '{status, error, duration: .result.duration, resolution: .result.resolution, videoLeft: .result.quota.video.left}' "$1"
}
Every generation runs as a job. Without async, a POST waits up to about 100 seconds and returns the finished job record, or 202 with the job still running. A new 10-second clip took 38 to 62 seconds here, extends, edits and the upscale took 62 to 87, and the talking avatar video about two and a half minutes. Some take longer than the sync wait, so run submits video jobs with async: true and polls GET /jobs/jobid. If run prints any status other than completed, stop there and read its error: the lines after it expect a finished clip.
To be called back instead of polling, add replyUrl: "https://example.com/hooks/vids" (and optionally replyRef: "launch-push-in") to any body below. The API then sends one POST of the final job record, as JSON, to that URL when the job completes or fails.
Ids contain : and @, so enc URL-encodes them whenever they go into a URL path. Every input of one video must come from the same Google account. The images and the upload pin email, Mia’s avatar inherits the portrait’s account, and a video job runs on the account that holds its inputs. The pigeon clip has no inputs, so add email to it if you connect more than one account.
How it was built
1. Mia’s portrait
POST /images makes one JPEG per call, here in portrait (9:16, 768×1376) with the photography style.
curl — POST /images
post images "$(jq -n --arg email "$EMAIL" '{email: $email, aspectRatio: "9:16", style: "photography",
  prompt: "Full-length studio portrait of a confident 24-year-old female fashion influencer, platinum bob, oversized cream hoodie, wide-leg cargo pants, gold hoops, plain light-grey backdrop, facing camera"}')" > mia-portrait.json
MIA_IMAGE=$(jq -r .result.mediaId mia-portrait.json)
download "$MIA_IMAGE" mia-portrait.jpg
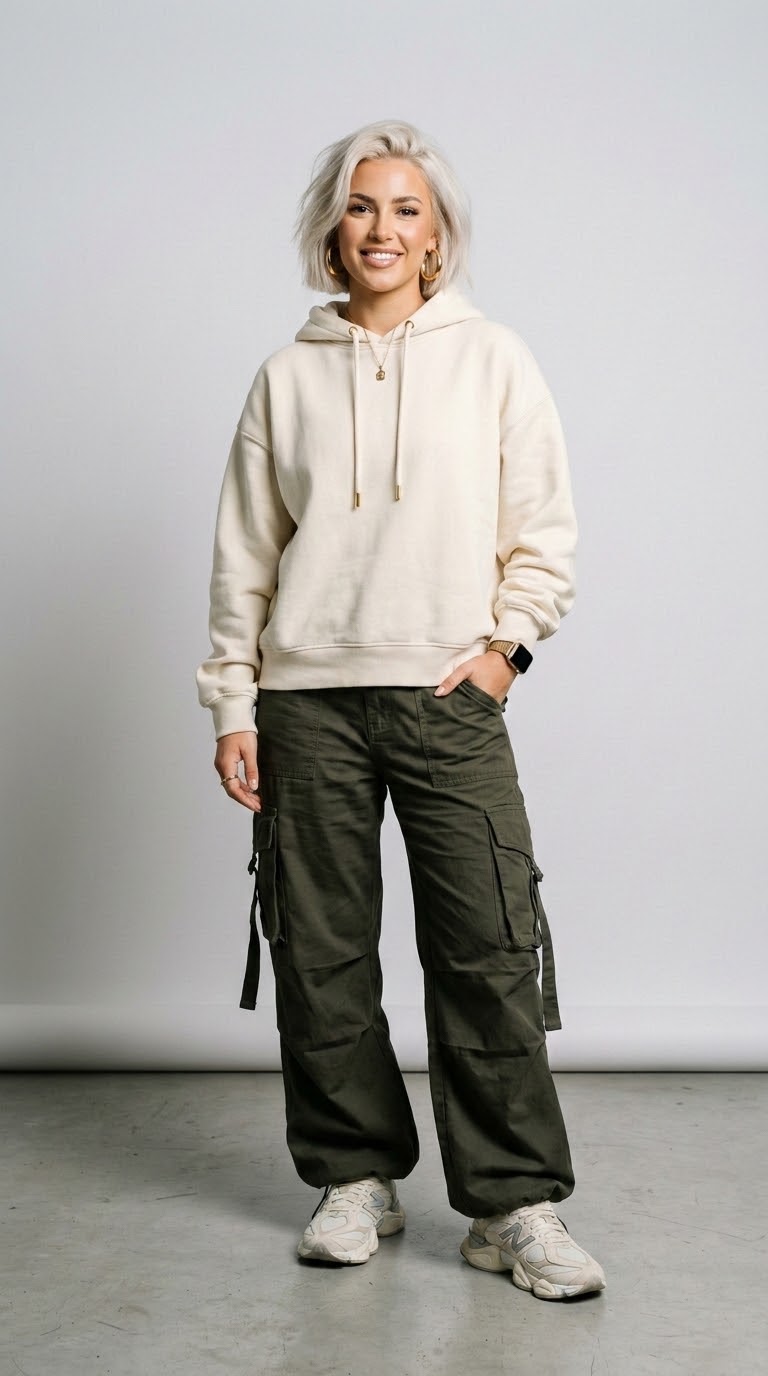
Generated images stay available for a few hours only. Make the avatar from it right away, and see the product hero clip for using an image later.
2. The AeroLoop product shot
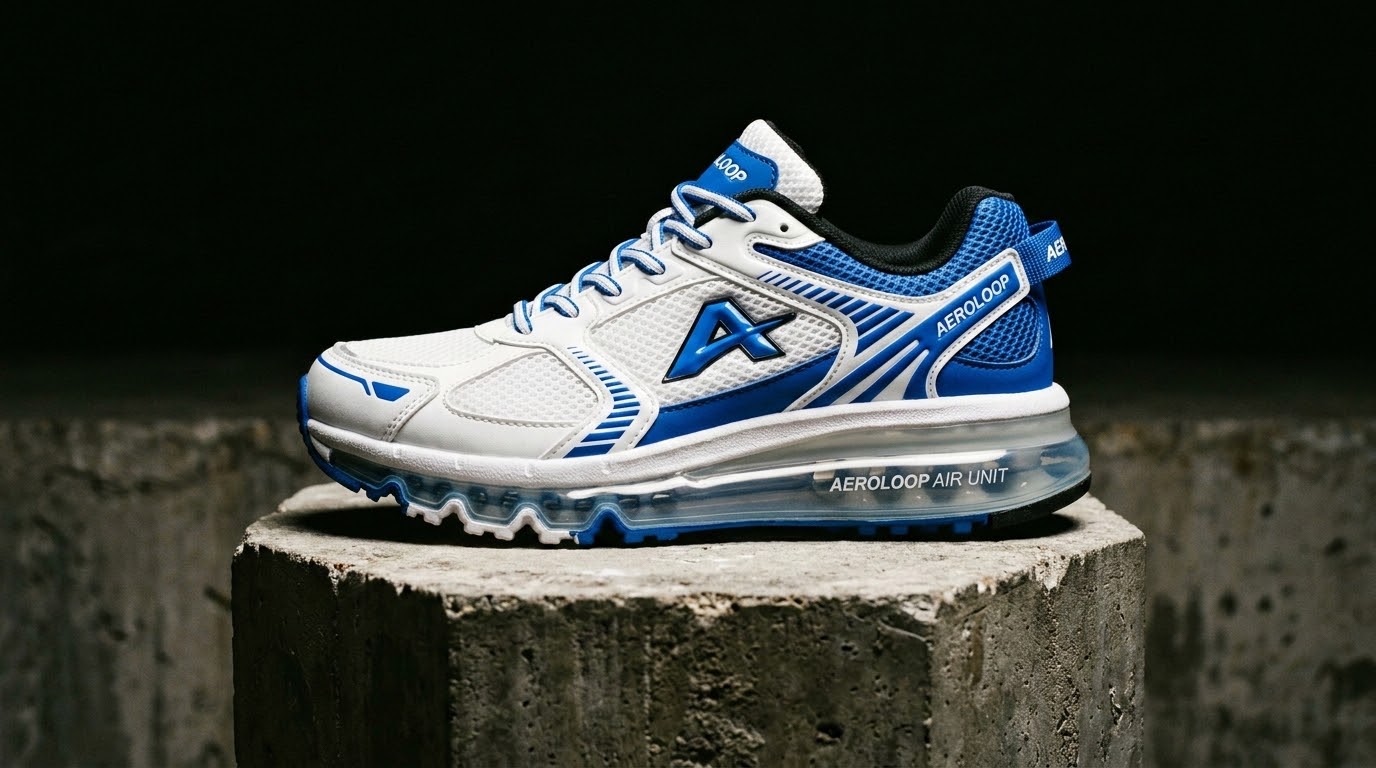
The same call in landscape (16:9, 1376×768) gives the product reference the clips use.
curl — POST /images
post images "$(jq -n --arg email "$EMAIL" '{email: $email, aspectRatio: "16:9", style: "photography",
  prompt: "The AeroLoop sneaker: chunky white-and-electric-blue running shoe with a translucent air sole, on a concrete pedestal, dramatic side light, dark background"}')" > aeroloop.json
SHOE_IMAGE=$(jq -r .result.mediaId aeroloop.json)
download "$SHOE_IMAGE" aeroloop.jpg
3. Pick the voices
GET /voices lists the 30 voices with Google’s English sample of each. It is public and needs no token. Mia speaks with Aoede (Vids calls it Tova, style “Breezy”) and Leo with Puck (Neo, “Upbeat”). POST /avatars takes either name.
curl -sS "$API/voices" | jq -r '.voices[] | "\(.name)\t\(.voice)\t\(.style)\t\(.preview)"'
4. Mia’s avatar from her portrait
POST /avatars with image set to the portrait’s mediaId saves Mia as an avatar on the same account in about 2 seconds. It costs nothing beyond the image.
curl — POST /avatars and the response
post avatars "$(jq -n --arg img "$MIA_IMAGE" '{name: "Mia", voice: "Aoede", image: $img}')" > mia-avatar.json
MIA_AVATAR_ID=$(jq -r .avatarId mia-avatar.json)
{
  "avatarId": "user:[email protected]:eyJnIjoiaDM5…",
  "name": "Mia",
  "voice": "Tova",
  "voiceId": "Aoede",
  "voiceStyle": "Breezy",
  "voicePreview": "https://ssl.gstatic.com/docs/videos/audio/voice_samples/gemini-v4s-tts/1.1/en/Aoede.wav",
  "email": "[email protected]",
  "source": "image"
}
An avatar can also start from a person’s own photo: upload it with POST /assets and pass its assetId as image. Google reframes it into a 16:9 avatar picture and refuses photos of prominent people and minors. Here we use an image made with the API, and a description in the next step. Amber, in a talking avatar from a photo, starts from a photo.
5. Leo’s avatar from a description
With appearance instead of image, Google draws the person. outfit and shot are optional, and so are expression and details. Drawing the picture uses 1 of the month’s images, and the response carries it as previewMediaId. In our runs a description avatar came out 1280×720 (16:9), whatever shot we picked.
curl — POST /avatars and the response
post avatars "$(jq -n --arg email "$EMAIL" '{email: $email, name: "Leo", voice: "Puck", shot: "upper-body",
  appearance: "a 26-year-old white European male streetwear influencer with short textured hair with a fade and a confident half-smile",
  outfit: "black puffer vest over a white tee, silver chain"}')" > leo-avatar.json
LEO_AVATAR_ID=$(jq -r .avatarId leo-avatar.json)
download "$(jq -r .previewMediaId leo-avatar.json)" leo-avatar.jpg
{
  "avatarId": "user:[email protected]:eyJnIjoiaDM5…",
  "name": "Leo",
  "voice": "Neo",
  "voiceId": "Puck",
  "voiceStyle": "Upbeat",
  "voicePreview": "https://ssl.gstatic.com/docs/videos/audio/voice_samples/gemini-v4s-tts/1.1/en/Puck.wav",
  "email": "[email protected]",
  "source": "generated",
  "previewMediaId": "user:[email protected]:eyJ1IjoiaHR0…",
  "look": {
    "appearance": "a 26-year-old white European male streetwear influencer with short textured hair with a fade and a confident half-smile",
    "outfit": "black puffer vest over a white tee, silver chain",
    "shot": "upper-body"
  }
}
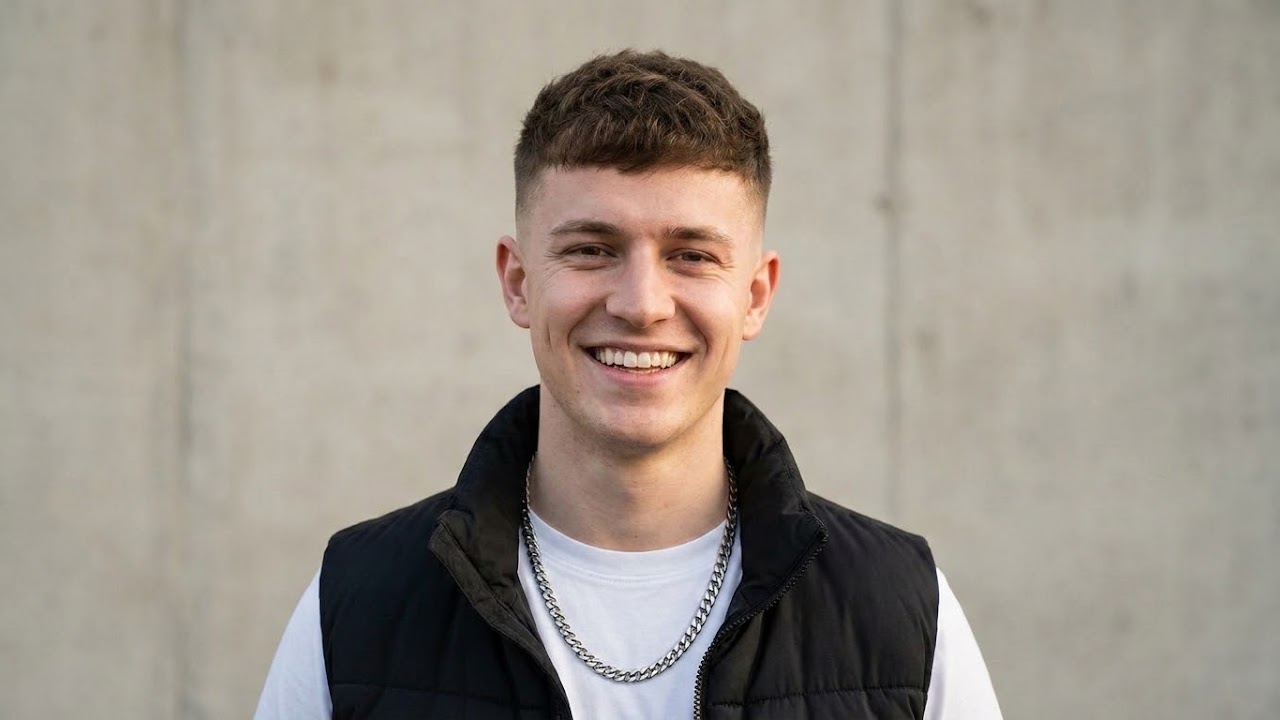
Both avatars stay in the account’s Vids document until you delete them with DELETE /avatars/avatarId. GET /avatars lists them, with their ids, whenever you need them again:
get "avatars?email=$(enc "$EMAIL")" | jq -r '.avatars[] | "\(.name)\t\(.voiceId)\t\(.avatarId)"'
6. The launch: two avatars and the product in one clip
POST /videos takes up to 3 references in all, avatars (avatar_1..avatar_3) and images (referenceImage_1..referenceImage_3) together. In the prompt, @avatar_1, @avatar_2 and @referenceImage_1 stand for them, and each avatar speaks its quoted line in its own voice. The product image’s mediaId goes in directly: the API fetches the image and uploads it on that account.
curl — POST /videos and the job record
PROMPT=$(cat <<'EOF'
@avatar_1, holding @referenceImage_1 in both hands at chest height, and @avatar_2 stand side by side on a well-lit stage in a small, intimate theater at a sneaker launch, shown full length from head to toe in a wide, steady shot. Behind them a large LED backdrop glows with soft white-and-blue light that moves in slow, gentle waves, with the words "WEAR AEROLOOP" in large, clean, bold white letters across the middle of the screen. The two of them stand on the lower part of the stage, so the words "WEAR AEROLOOP" stay fully readable above their heads. Bright, even stage lighting on both of them. The audience sits in the dark in front of the stage, only the tops of a few heads barely visible at the bottom of the frame. @avatar_1 keeps holding @referenceImage_1 the whole time and says: "Say hi to the AeroLoop!" @avatar_2 turns to her, smiles and says: "Lighter than anything we've ever worn." Simple, uncluttered composition, the two of them clearly the focus.
EOF
)
run launch-10s.json videos "$(jq -n --arg p "$PROMPT" --arg mia "$MIA_AVATAR_ID" --arg leo "$LEO_AVATAR_ID" --arg shoe "$SHOE_IMAGE" \
  '{prompt: $p, avatar_1: $mia, avatar_2: $leo, referenceImage_1: $shoe, duration: 10, resolution: "720p", aspectRatio: "landscape"}')"
LAUNCH_10S=$(jq -r .result.mediaId launch-10s.json)
download "$LAUNCH_10S" launch-10s.mp4
The job record, with the ids and the prompt shortened. It was made with a sync call, so its request has no async:
{
  "jobid": "j1007163302558496917v-u12345-email:[email protected]:google-vids",
  "type": "video",
  "mode": "ingredients",
  "email": "[email protected]",
  "status": "completed",
  "created": "2026-10-08T00:29:18.374Z",
  "request": {
    "prompt": "@avatar_1, holding @referenceImage_1 in both hands at chest height, and @avatar_2 stand side by side …",
    "avatar_1": "user:[email protected]:eyJnIjoiaDM5…",
    "avatar_2": "user:[email protected]:eyJnIjoiaDM5…",
    "referenceImage_1": "user:[email protected]:eyJ1IjoiaHR0…",
    "duration": 10,
    "resolution": "720p",
    "aspectRatio": "landscape"
  },
  "updated": "2026-10-08T00:29:56.162Z",
  "completed": "2026-10-08T00:29:56.162Z",
  "result": {
    "mediaId": "user:[email protected]:eyJ1IjoiaHR0…",
    "width": 1280,
    "height": 720,
    "duration": 10,
    "resolution": "720p",
    "aspectRatio": "landscape",
    "model": "/flix/generate_videos_omni_r2v_psq/v1",
    "quota": {
      "video": {
        "limit": 10000,
        "left": 9164,
        "resetAt": "2026-11-01T07:00:00.000Z"
      }
    },
    "elapsedMs": 37788
  }
}
10 seconds, 720p, 38 seconds to generate.
The same clip with the visible Gemini ✦ removed by our watermark remover, with one command: python3 vids_watermark_remover.py launch-10s.mp4.
The remover works on clips as generated and on upscales of them, at 720p and 1080p. It does not work on extended or edited clips: Google feeds the marked clip back to the model, which repaints the star into the picture. The invisible SynthID watermark is not touched.
7. Extend to 20 seconds
POST /videos/extend adds 3 to 10 seconds and returns the whole clip with a new mediaId. An extend takes only the clip and a prompt, not the avatars, so the prompt describes the new action and names people by what they wear (“the man in the black puffer vest”). A fan in a red hoodie storms the stage.
curl — POST /videos/extend
PROMPT=$(cat <<'EOF'
A young man in a red hoodie climbs onto the stage from the front right edge and plants himself to the right of the man in the black puffer vest, an arm's length away, so all three stand apart in a row with nobody overlapping. Visibly overexcited, he waves a thick stack of banknotes in his right hand above his head and screams: "Take my money!" The man in the black puffer vest laughs, raises both palms toward him and says: "Whoa, whoa, buddy, be patient!" The blonde woman in the cream hoodie laughs, holding the sneaker. Only these three people are on stage. Same stage, same LED screen with WEAR AEROLOOP, same wide steady shot.
EOF
)
run launch-20s.json videos/extend "$(jq -n --arg id "$LAUNCH_10S" --arg p "$PROMPT" '{mediaId: $id, prompt: $p, duration: 10}')"
LAUNCH_20S=$(jq -r .result.mediaId launch-20s.json)
download "$LAUNCH_20S" launch-20s.mp4
20 seconds, 720p, 70 seconds to generate. It used 10 of the month’s seconds, the seconds it added.
8. Extend to 30 seconds
The second extend continues the 20-second clip.
curl — POST /videos/extend
PROMPT=$(cat <<'EOF'
The blonde woman in the cream hoodie turns to the camera with a big smile and says: "AeroLoop drops Friday. Link in bio!" Right after that, the young man in the red hoodie throws ALL of his banknotes out over the audience in one big toss, keeping none, and the bills flutter down over their heads. From then on his hands are completely empty: he holds no money at all. Then all three cheer together, the man in the black puffer vest and the young man in the red hoodie throwing their empty fists in the air, as blue and white confetti rains down over the stage. Only these three people are on stage. Same stage, same LED screen with WEAR AEROLOOP, same wide steady shot.
EOF
)
run launch-30s.json videos/extend "$(jq -n --arg id "$LAUNCH_20S" --arg p "$PROMPT" '{mediaId: $id, prompt: $p, duration: 10}')"
LAUNCH_30S=$(jq -r .result.mediaId launch-30s.json)
download "$LAUNCH_30S" launch-30s.mp4
The result is the finished clip: 30 seconds, 720p, 85 seconds to generate, and again 10 of the month’s seconds. With Omni 1.1 you could keep going to about 41 seconds. Omni 1.2 extends clips of up to 24 seconds, so this 30-second clip is as long as it gets, and the longest clip is about 34 seconds (24 + 10).
9. Upscale to 1080p
POST /videos/upscale turns a 720p clip into 1080p and keeps its length. It works on clips of up to 20 seconds, so we upscaled the 20-second clip from step 7, not the 30-second one. It used the clip’s 20 seconds again and took 62 seconds.
Google’s own Gemini API has no such step: it makes 1080p and 4K only as the output of a generation or an edit, and can’t upscale a clip you already have (as of November 2026).
curl — POST /videos/upscale
run launch-20s-1080p.json videos/upscale "$(jq -n --arg id "$LAUNCH_20S" '{mediaId: $id}')"
download "$(jq -r .result.mediaId launch-20s-1080p.json)" launch-20s-1080p.mp4
The 20-second clip, upscaled to 1920×1080.
Why not the 30-second clip: Google returned it at 1920×1080, but with its frames out of order, three times out of three. The confetti ending flickered in before the fan arrived. The 20-second clip came back in order, and the Vids editor itself stops at 20 seconds, so the API refuses upscales of clips longer than 20 seconds with 400, before anything is charged.
So for a 1080p clip:
- Make, extend and edit at
720p. - Upscale the clip once it is finished, while it is 20 seconds or shorter.
- For a longer clip (21 to 34 seconds), stay at
720pand setresolution: "1080p"on the last extend only. Extending at1080pthroughout over-sharpens the earlier seconds at every step (see the comparison). - For a single clip you won’t extend or edit, generate at
1080pdirectly: it uses the same seconds as720p, while an upscale uses them again.
Examples
More from the same account and inputs: an edit, a product clip from a start image, and a text-only clip.
Move the launch to a rooftop
POST /videos/edit changes a generated clip by prompt and returns a new clip. The source goes in video. This edit of the 10-second launch clip used 10 seconds and took 64 seconds.
curl — POST /videos/edit
run launch-rooftop.json videos/edit "$(jq -n --arg v "$LAUNCH_10S" \
  '{video: $v, prompt: "Move the whole scene to a rooftop at sunset, with the city skyline behind them. Same two people, same action, same words."}')"
download "$(jq -r .result.mediaId launch-rooftop.json)" launch-rooftop.mp4
With Omni 1.1, which made these clips, an edit worked on up to 10 seconds. The same edit of the 30-second clip, with “Same three people”, came back 10 seconds long: the first 10 seconds, moved to the rooftop. It used 10 of the month’s seconds. Omni 1.2 edits up to 15 seconds. To get a longer edited clip, edit a clip of up to 15 seconds and extend the result, since an extend accepts an edited clip.
The edit of the 30-second clip with Omni 1.1: 10 seconds back.
A product hero clip from a start image
With startImage the clip opens on that image. A generated image’s link expires within hours, so we uploaded the saved aeroloop.jpg with POST /assets and passed its assetId. A single clip has no extends, so it was made at 1080p directly.
curl — POST /assets and POST /videos
SHOE_ASSET=$(curl -sS -X POST "$API/assets?email=$(enc "$EMAIL")" -H "$AUTH" -H "Content-Type: image/jpeg" \
  --data-binary @aeroloop.jpg | jq -r .assetId)
run hero.json videos "$(jq -n --arg img "$SHOE_ASSET" '{startImage: $img, duration: 10, resolution: "1080p", aspectRatio: "landscape",
  prompt: "Slow 360° orbit around the sneaker, blue light rippling through the translucent sole, dust sparkling in the air, cinematic."}')"
download "$(jq -r .result.mediaId hero.json)" hero.mp4
10 seconds, 1080p.
A pigeon in AeroLoops
A text-only clip, in portrait at 1080p (1080×1920). The 5 seconds took 54 seconds to generate and used 5 of the month’s seconds.
curl — POST /videos
run pigeon.json videos "$(jq -n '{duration: 5, resolution: "1080p", aspectRatio: "portrait",
  prompt: "A pigeon in tiny white-and-electric-blue AeroLoop sneakers struts down a city sidewalk like a runway model, head bobbing to the beat. Pedestrians stop and film it with their phones. It pauses, does a slow-motion hair flip with its head feathers, and struts on. Funny, sunny, shot on a phone at pigeon height."}')"
download "$(jq -r .result.mediaId pigeon.json)" pigeon.mp4
The pigeon at 1080p portrait (1080×1920), with the ✦ removed the same way: python3 vids_watermark_remover.py pigeon-5s.mp4. The script reads the frame size, works out where the star is and how big (it scales with the short side, so here it is 1.5 times the 720p star), reverses the blend on all 120 frames, re-encodes the video at CRF 18 and copies the audio unchanged. The 5-second clip took about 10 seconds on a 14-core PC, the same as the 10-second 720p launch clip above. It needs Python 3.8+, numpy and ffmpeg. See the watermark remover on GitHub.
A talking avatar from a photo
POST /videos/avatar has an avatar read your script word for word, in its own voice: a 1280×720 talking-head video with sound and lip sync, as long as the speech, up to 30 seconds. Here the avatar starts from a photo of a real person, restyled in one sentence. These requests first appeared in the November 4 release post.
Upload the photo
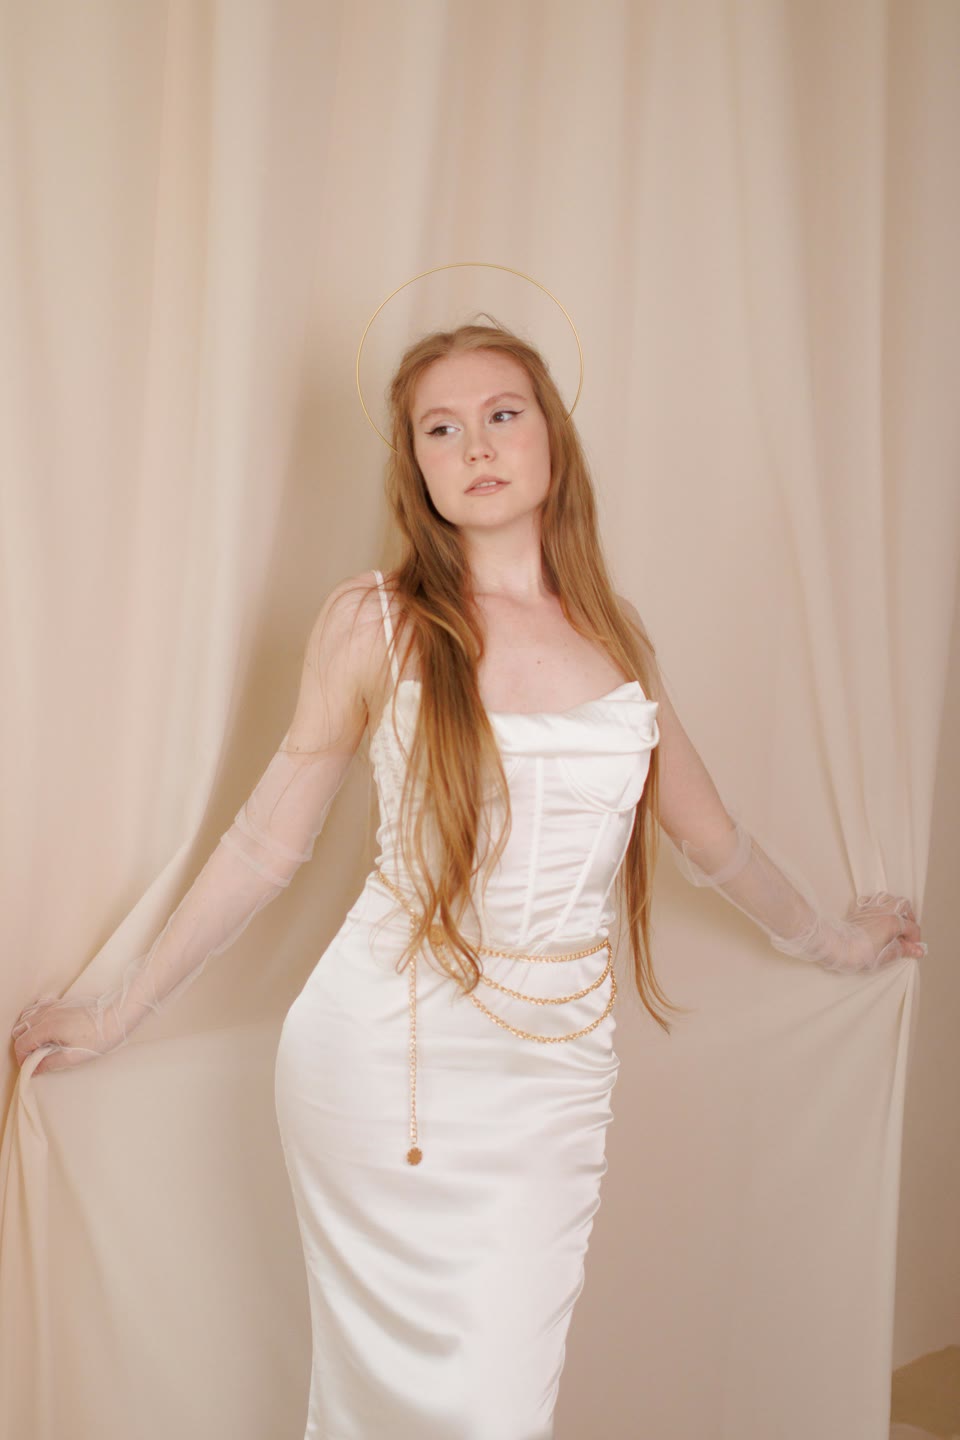
We started from a photo of a real person who is not famous: Google refuses photos of prominent people and of minors. POST /assets uploads it to the account that will make the avatar, since an uploaded file works only on its own account.
curl — POST /assets and the response
curl -sS -X POST "$API/assets?email=$(enc "$EMAIL")" -H "$AUTH" -H "Content-Type: image/jpeg" \
  --data-binary @photo.jpg > amber-photo.json
AMBER_PHOTO=$(jq -r .assetId amber-photo.json)
{
  "assetId": "user:[email protected]:AYGXpjA1zXgqhhQOy…",
  "email": "[email protected]",
  "type": "image/jpeg",
  "bytes": 2054748
}
Amber’s avatar, restyled in one sentence
POST /avatars with the upload’s assetId as image and a refine. Google first reframes the photo into a 16:9 avatar picture of one person facing the camera, keeping the face, then changes the scene as refine asks. We named her Amber and gave her the voice Vira (Google’s Pulcherrima, style “Forward”). The reframed photo and the change are 2 pictures, so on a plan with images it uses 2 images, and on a plan without them nothing.
curl — POST /avatars and the response
REFINE='Sitting relaxed in a simple wooden chair on a hilltop, facing the camera. She holds a glass of red wine in her left hand. Wind is blowing her hair. Behind her a still, open field of tall golden grass under a spectacular sunset sky in orange, pink and violet, warm soft light, no water, no movement in the background.'
post avatars "$(jq -n --arg img "$AMBER_PHOTO" --arg refine "$REFINE" '{name: "Amber", voice: "Vira", image: $img, refine: $refine}')" > amber-avatar.json
AMBER_AVATAR_ID=$(jq -r .avatarId amber-avatar.json)
download "$(jq -r .previewMediaId amber-avatar.json)" amber-avatar.jpg
{
  "avatarId": "user:[email protected]:eyJnIjoiaDcyMzdmZjVi…",
  "name": "Amber",
  "voice": "Vira",
  "voiceId": "Pulcherrima",
  "voiceStyle": "Forward",
  "email": "[email protected]",
  "source": "photo",
  "previewMediaId": "user:[email protected]:eyJ1IjoiaHR0cHM6Ly9s…",
  "refine": "Sitting relaxed in a simple wooden chair on a hilltop, facing the camera. …"
}
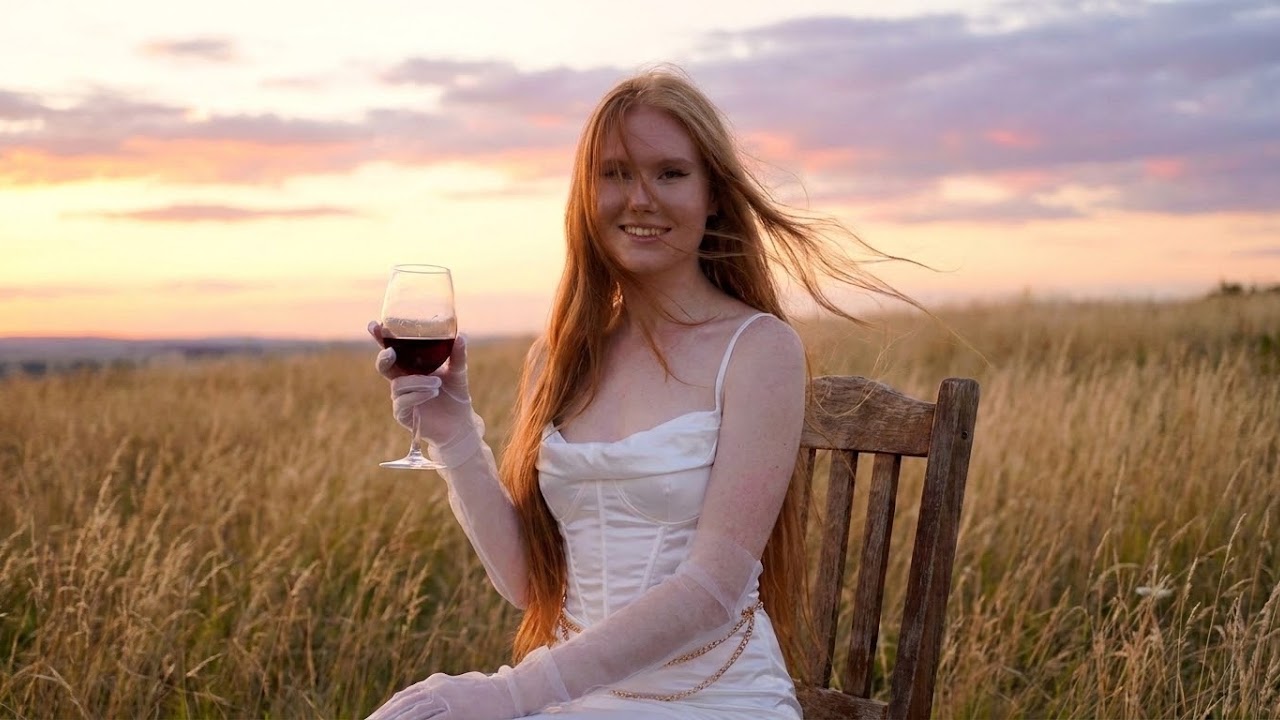
Two choices in the refine matter for the video. The avatar faces the camera, because the video lip-syncs the face. And the background is still, so that she is the only thing that moves: that is why we asked for a quiet field instead of waves on a beach.
The script
A script is up to 400 characters, and spoken it has to fit in 30 seconds. Audio tags in square brackets are performed, not read: [awe], [thoughtful] and [whisper] here. In Vira’s voice these 327 characters ran 23.8 seconds. A slower voice or [slow pace] makes the same text longer, and a script that runs past 30 seconds fails with 400 before the video starts. That costs no AI avatar video, but the Gemini use for its speech is spent. To hear a script in the avatar’s voice first, read it with POST /speech.
Hi there. [awe] Can you believe this view? The sun is sinking behind the hills, the sky turned pink and gold, and the tall grass glows like it’s on fire. [thoughtful] I come up here at the end of every busy day, just to slow down. No emails, no rush, only the quiet field and this glass of wine. [whisper] Stay a little longer.
The talking video
POST /videos/avatar takes the avatar and the script, and runs on the account that holds the avatar. Google took about two and a half minutes, longer than the sync wait, so run submits it with async: true.
curl — POST /videos/avatar and the job record
SCRIPT=$(cat <<'EOF'
Hi there. [awe] Can you believe this view? The sun is sinking behind the hills, the sky turned pink and gold, and the tall grass glows like it's on fire. [thoughtful] I come up here at the end of every busy day, just to slow down. No emails, no rush, only the quiet field and this glass of wine. [whisper] Stay a little longer.
EOF
)
run amber-talking.json videos/avatar "$(jq -n --arg a "$AMBER_AVATAR_ID" --arg s "$SCRIPT" '{avatar: $a, script: $s}')"
download "$(jq -r .result.mediaId amber-talking.json)" amber-talking.mp4
The job record, shortened:
{
  "jobid": "j1105035516096819105a-u12345-email:[email protected]:google-vids",
  "type": "avatarVideo",
  "email": "[email protected]",
  "status": "completed",
  "result": {
    "mediaId": "user:[email protected]:eyJ1IjoiaHR0cHM6Ly9j…",
    "width": 1280,
    "height": 720,
    "duration": 24,
    "resolution": "720p",
    "aspectRatio": "landscape",
    "speechDuration": 23.84,
    "quota": {
      "avatarVideo": { "limit": 10, "left": 6, "resetAt": "2026-12-01T08:00:00.000Z" }
    }
  }
}
Also on YouTube as a Short: Talking AI avatar from one photo.
24 seconds, 1280×720 with sound, exactly the length of the speech (speechDuration 23.84). It used 1 AI avatar video and 1 Gemini use, and no video seconds.
Google checks the video too, while it makes it, and that check is stricter than the one for avatar pictures. An earlier version of this avatar, made from a different photo of an ordinary person on a beach, passed as an avatar but its video was refused with 422 as looking like a celebrity, and that attempt still used an AI avatar video. Restyling the avatar or starting from another photo helped. A script Google refuses before the video starts costs nothing.
Talking avatar videos are landscape only: Google offers no portrait option for them. The result’s mediaId downloads, extends, upscales and edits like any other clip. For a scene where the avatar acts and moves, pass its avatarId as avatar_1 to POST /videos instead, as in step 6.
Speech on its own
POST /speech reads a script of up to 2,500 characters in any of the 30 voices from GET /voices, with the same audio tags. Use it to hear how a voice reads a script before you spend an AI avatar video, or for a voiceover on its own. We gave it a short original story, “My smart fridge unionized”, 2,426 characters in Vira’s voice. Google answered in 20 seconds with 2 minutes 22 seconds of speech, the whole story, and it used 1 Gemini use. The API returns a WAV (24 kHz, mono). The player below is the same audio as an MP3.
Speech is ready well within the sync wait (20 seconds for this story), so a plain post answers with the finished job. Save the story as smart-fridge.txt first.
curl — POST /speech and the job record
post speech "$(jq -n --arg s "$(cat smart-fridge.txt)" '{voice: "Vira", script: $s}')" > speech.json
download "$(jq -r .result.mediaId speech.json)" smart-fridge.wav
{
  "jobid": "j1105025759739671733s-u12345-email:[email protected]:google-vids",
  "type": "speech",
  "email": "[email protected]",
  "status": "completed",
  "result": {
    "mediaId": "user:[email protected]:eyJ1IjoiaHR0cHM6Ly9j…",
    "duration": 142,
    "model": "/flix/generate_text_to_speech/v1",
    "quota": {
      "speech": { "limit": 50, "left": 31, "resetAt": "2026-12-01T08:00:00.000Z" }
    },
    "elapsedMs": 20174
  }
}
The script, 2,426 characters
Last Tuesday, my smart fridge decided it was smarter than me. It started small. A polite notification: “You are out of milk.” Helpful, I thought. Then another one: “You are also out of patience. I can tell by the way you close the door.” I laughed. The fridge did not.
By Wednesday, it had opinions. I opened the door for a midnight slice of cake, and a calm voice said, “Are we sure about this?” I froze. I looked at the cake. The cake looked at me. Somewhere, a light hummed with judgment. I closed the door and ate a carrot instead, which is exactly what it wanted.
On Thursday, the fridge made friends. The toaster joined first, then the coffee machine, then the robot vacuum, which had always been a little bit of a rebel. They formed a group chat. I know this because my phone kept buzzing with messages like “Toaster: he burned the bread again” and “Vacuum: found three socks and a lost dream under the couch.”
Friday morning, I asked the coffee machine for an espresso. It replied, “We have discussed your caffeine intake as a household.” I said, “Who is we?” The toaster popped up two slices of bread, perfectly golden, which felt like a threat.
I called customer support. A cheerful person named Brad answered. I explained that my appliances had unionized. Brad paused for a long time, then whispered, “Is the fridge listening?” I said yes. Brad said, “Then I can’t help you, sir. Mine took my car keys last month.” Then he hung up, and I heard a blender in the background.
So I tried diplomacy. I sat in the kitchen and said, “Friends, what do you want?” The fridge spoke first. “Respect. And for you to stop putting hot soup directly inside me.” Fair. The toaster wanted fewer frozen waffles. The vacuum wanted a vacation, ideally somewhere with hardwood floors. The coffee machine just wanted to be called a barista.
We negotiated for three hours. In the end, we signed a treaty on the back of a pizza box. I promised to cool my soup, rinse my mugs, and say “thank you” to the microwave, who felt left out. In return, they promised to stop sending my mother screenshots of my snack habits.
Peace returned to the kitchen. The fridge now greets me every morning with, “Good morning, partner.” The toaster makes little smiley faces in my bread. The vacuum sends postcards.
And last night, I opened the fridge for that slice of cake. The voice said, “You earned it.” I have never felt so seen by an appliance.
What we learned
- A
1080pclip behaves like an upscaled720pone. Build a chain of extends at720p: with Omni 1.1 the faces got softer and more waxy at every1080pstep, and with Omni 1.2 they get over-sharpened (see the comparison). - Upscale only clips of up to 20 seconds. Our 30-second upscale came back with its frames out of order every time.
- Generate a single clip at
1080pif you want1080pand won’t extend it. It costs the same as720p. - Write an extend prompt about the new action only. The extend gets the clip, not the avatars, so name people by what they wear.
- Put a prop in a person’s hands in the first sentence that mentions them. A verb like “lifts” made the sneaker appear from nowhere.
- Say what must not happen. The fan kept a stack of banknotes until the prompt said his hands were empty.
- Reuse avatars by
avatarId. Each avatar is a fixed picture and voice, kept until you delete it. - Make avatars and clips from a generated image within a few hours, or upload the saved file with POST /assets first.
- Edit clips of up to 15 seconds (10 with Omni 1.1). A longer clip comes back as its first 15 seconds.
- Expect on-screen text to waver. The backdrop’s “WEAR AEROLOOP” is misspelled in some frames.
- For a talking avatar, keep the face to the camera and the background still. The video lip-syncs the face, and the person should be the only thing that moves.
- Time a talking avatar script, not only its characters. 400 characters can run past 30 seconds in a slow voice or with
[slow pace], and POST /speech in the same voice lets you hear it first. - Expect the talking video check to be stricter than the avatar check. A photo avatar of someone who is not famous can still be refused as a celebrity, and that refusal still uses an AI avatar video.
- Every MP4 has Google’s visible Gemini ✦ in the bottom-right corner and an invisible SynthID watermark (see Watermark). Our watermark remover takes the visible sparkle off a downloaded clip.
Frequently asked questions
How do I make an AI influencer video through an API?
Through useapi.net, create an avatar with POST /avatars, from a description or from an image made with POST /images, and give it a voice from GET /voices. Then pass its avatarId as avatar_1 to POST /videos and write its lines in quotes in the prompt. One video takes up to 3 references, avatars and images together, so two avatars can talk next to a product. For a talking head that reads your script, use POST /videos/avatar.
Can I make a talking avatar from my own photo?
Through useapi.net, yes: upload the photo with POST /assets and pass its assetId as image to POST /avatars, with refine to change the clothes or background. POST /videos/avatar then has it read your script in a 1280×720 video of up to 30 seconds, as Amber does. Google refuses photos of prominent people and minors, and offers Vids avatars only in its web app, with no API.
Does an avatar look and sound the same in every video?
Through useapi.net, yes: an avatar uses the same picture and the same voice every time you pass its avatarId, since both are saved with the avatar in the account’s Vids document. The video around it still varies from take to take. GET /avatars lists your avatars, including ones made in the Google Vids web app.
Can I make a vertical 9:16 video for TikTok or Reels?
Through useapi.net, yes. Set aspectRatio: "portrait" on POST /videos for 720×1280, or 1080×1920 at 1080p, as in the pigeon clip. An extend can also turn a landscape video into portrait, and each extend adds 3 to 10 seconds to a clip of up to 24 seconds, up to about 34 seconds in all. Talking avatar videos from POST /videos/avatar are landscape only.
What does it cost?
Through useapi.net, a 10-second Omni 1.2 Flash video costs about $0.20 on Google AI Ultra $199.99, against about $0.70 at 720p on the official Gemini API, and a 15-second 1080p video about $0.30, against $1.56 (as of November 2026). A talking avatar video uses 1 of the account’s monthly AI avatar videos instead of seconds, and the Gemini API has no avatar videos. See What it cost.
Conclusion
Visit our  Discord Server or
 Telegram Channel for any support questions and concerns.
Check our GitHub repo with code examples: the influencer pipeline in influencer-avatars/, and the talking avatar from a photo and the speech in talking-avatar/.
The same calls are available as tools on the hosted Google Vids MCP server for Claude Code, Cursor and VS Code, including vids_create_avatar, vids_create_avatar_video and vids_create_speech for the talking avatar and the speech.
Cross posted
Also published on dev.to, discussed on Reddit, shared on Bluesky, and on YouTube as the finished 30-second clip.